October 13, 2026Main stage4 min read

Shipping like a startup, regulated like a bank

David Abitbol describes Revolut’s move toward self-hosted coding models, the inference tuning that made them practical, and the operational controls used around a regulated engineering organization.

David AbitbolRevolutOps & Infrastructure Leader

From the conference livestream · 5:36:54–5:48:28 on YouTube. The player starts and stops at this session’s boundaries.

5:36:55 ↗

The engineering bottleneck was bigger than coding time

An engineer can write code faster and still spend days moving a feature toward deployment. David Abitbol opens Revolut’s AI story with two measures from a sample of about 2,000 engineers: coding time, measured in hours, and lead time from picking up a feature to having it merged and ready to deploy, measured in days.

Early use of Gemini helped with looking up information and reading documentation. Abitbol reports improvements in both measures. The initial rollout of Claude Code was less compelling economically: some engineers consumed substantial token budgets without a similarly clear return, so the company imposed limits.

That created a second problem. When tokens feel scarce, engineers save them for a difficult coding task instead of using them across the surrounding work. Abitbol describes self-hosting GLM models as a way to give engineers much more freedom to use AI without unpredictable bills.

He reports that the move to GLM 5.1 coincided with roughly 60% better coding time and 70% better lead time on Revolut’s chart. The internal comparison does not isolate the model change from other causes. His interpretation is that engineering delays include the inbox, Jira, Confluence, and other work around the code. Cheaper access broadens which tasks people are willing to delegate.

5:40:47 ↗

Tune the same GPUs before buying more

Open models became Revolut’s default for this workload, with frontier services kept available for exceptions. Abitbol reports using 56 B200 GPUs to serve GLM 5.3 to roughly 2,000 engineers. His target is a time to first token below three seconds; once it exceeds five, users start complaining. Around 200 tokens per second is adequate for the interactive workload he describes, especially as engineers increasingly launch tasks in parallel and return when they finish.

The economics he reports are a blended cost near $0.30 per million tokens and spending around a tenth of the prior Anthropic/OpenAI invoice. Those figures describe Revolut’s deployment and utilization, not a portable price for any self-hosted model.

Simply loading weights onto GPUs did not deliver the desired performance. The team tuned its serving system against actual demand. The chart below holds the GPU count constant while showing higher request volume and lower latency.
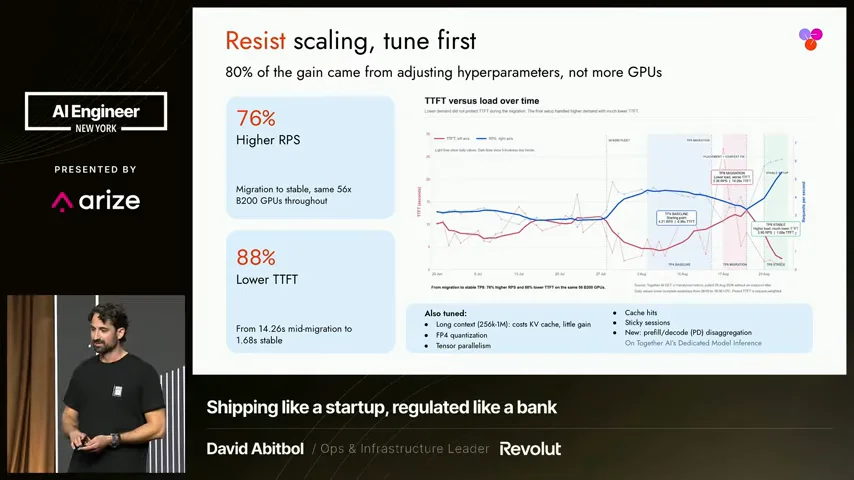
Revolut’s tuning slide reports 76% higher requests per second and 88% lower time to first token on the same 56 B200 GPUs.

At 5:43:39, the slide reports 76% higher requests per second and an 88% reduction in time to first token, from 14.26 seconds during migration to 1.68 seconds in the stable setup. Abitbol’s advice is to resist adding GPUs until the existing configuration has been tuned.

5:43:52 ↗

Context, cache, and the shape of inference

The context window competes with concurrent requests for GPU memory. The KV cache stores attention data from tokens already processed, so the model can reuse it while generating the answer. Reserving room for the maximum advertised context may waste capacity when most coding requests are smaller. Abitbol sizes the window to the work engineers actually send.

Quantization can reduce the GPU memory footprint. He favors FP4 on the Blackwell-generation hardware in this deployment. Tensor parallelism also affects the tradeoff: fitting the weights across four GPUs does not necessarily leave enough KV-cache space for the workload, so an eight-way configuration can perform better.

Cache reuse is especially valuable when coding tasks repeatedly carry similar context. He advises checking the cache-hit rate, then considering techniques such as speculative decoding and separating prefill from decode. Prefill processes the input context; decode generates the answer token by token. Their different workloads create opportunities to tune or separate the serving stages.

The production application still needs to handle capabilities outside the main model. For a text-only coding model, Abitbol suggests routing image understanding to another model rather than sacrificing coding quality just to keep every task on one endpoint. Compatible APIs then let engineers use their preferred coding harness against the hosted models.

5:46:10 ↗

Keep control around the model

Abitbol finishes with the operational case for self-hosting. Downloading weights and running them on infrastructure selected by the company is a different data path from sending inference requests to a model developer’s hosted service. The deployment choice matters more than the model’s country of origin alone.

He describes Revolut’s approach to human oversight: configure the sandbox and approval rules so restricted operations require intervention. The rules constrain what a coding agent can actually execute, rather than relying on a promise that a human will review everything later. He also discusses misuse by insiders and prompt injection as concerns for the surrounding controls.

His comments about regulatory classification and acceptable hosting locations describe his view of Revolut’s circumstances. They should not be read as a general determination that a model, region, or sandbox automatically satisfies another organization’s obligations.

The final requirement is observability. If an incident occurs, the team needs enough telemetry to inspect what happened and follow it through the system. That same data supports operational analysis during ordinary use. Lower inference costs let engineers use the model more freely. Sandbox rules limit what it can do, and telemetry lets the team investigate when something goes wrong. Self-hosting leaves Revolut responsible for all three.

Full transcript 202 timestamped passages

Machine transcription with reviewed terminology and names. Some recognition errors may remain. Timestamps refer to the livestream; subtitle downloads are timed to the session clips.

5:36:55Hello everyone, welcome.

5:36:59My name is David.

5:37:01I lead AI operations at a company called Revolut.

5:37:05We have 15 minutes today together.

5:37:09we'll talk about high performance engineering and self-hosting open source model on dedicated GPU.

5:37:15How does that sound?

5:37:18Cool.

5:37:19So it's going to be a technical one, so bear with me.

5:37:22So maybe to start off, because I know this is the US and you may not know Revolut,

5:37:28quick words about our company.

5:37:31We're a digital bank in Europe.

5:37:33We have 80 million customers.

5:37:35We're live in 45 markets.

5:37:38with the most downloaded financial app in Europe for the last year.

5:37:43And as of July, we're Europe's largest private company.

5:37:49So we're doing okay.

5:37:53The emphasis of Revolut is shipping a lot of product,

5:37:56and so there's a high focus on engineering culture and excellence on that demand.

5:38:02And so we'll talk about that.

5:38:05So let's talk about some AI.

5:38:09We have a chart here.

5:38:10I'm going to see two lines.

5:38:12This is a sample of 2,000 engineers' performance over the last year.

5:38:17So the green line is going to be lead time.

5:38:20So it's going to be when an engineer picks up a feature

5:38:23until a feature is merged and ready to be deployed.

5:38:28The blue line is going to be coding time.

5:38:30So the green line is in days.

5:38:31The blue line is in hours.

5:38:35Just to reset the timeline in case people forget,

5:38:37because AI moves really fast.

5:38:39Claude Code came out around February 2025, right?

5:38:43And that's the Claude Code, Sonnet 3.7,

5:38:46the one that would delete your prod database, right?

5:38:49Not the safe cloud and codex that we have today.

5:38:52So bear in mind when we talk about adoption.

5:38:55So what you see on this chart is January 25,

5:38:59first introduced AI in the company, right?

5:39:01Gemini.

5:39:02First time people were able to use private data within AI.

5:39:08Around February, we started playing around with Claude Code, and then January is when

5:39:12we first launched Claude Code at scale.

5:39:16What you see is Gemini had 10% improvement in lead time, 20% improvement in coding time,

5:39:22so that's people no longer need to look at Stack Overflow and reading documentation.

5:39:27But then Claude Code, not so much impact at the time.

5:39:31So when we launched it, we were highly skeptical about the cost of AI.

5:39:36we were seeing engineers spend a thousand a month,

5:39:3910,000 a month with not so much ROI.

5:39:41And so when we launched it,

5:39:43we launched it with strict budget limits.

5:39:47And so we're looking at the next thing, right?

5:39:48So how can we provide limited tokens to our engineers

5:39:51so they can use AI guild-free for a fraction of the cost?

5:39:55And so we looked into open source.

5:39:58So around April 26 is when we started

5:40:00self-hosting open source model.

5:40:02We're a big fan of GLM for coding.

5:40:05so around that time what you see

5:40:06April 26th, GLM 5.1

5:40:10we see 60% improvement

5:40:12in coding time

5:40:1470% improvement in lead time

5:40:17so traumatic impact

5:40:20what do we learn from this?

5:40:21well there's more impact on the lead time

5:40:22than on the coding time

5:40:23so what we find is the bottleneck for engineering

5:40:26is not necessarily coding

5:40:29you can save a lot of time

5:40:30not having to dig through your inbox

5:40:32or messing with Jira and Confluence

5:40:34and so when you have a limited token you're free to do that. You no longer have to save

5:40:39your tokens for the end of the quarter or the most difficult task. So where do we stand?

5:40:47Well open source is now a priority, a revolute, and your economics are favorable, the billing

5:40:53is flat, we don't have any bill shock any of the month, and the frontier is the exception.

5:40:59So obviously we keep using codex, code code.

5:41:02The latest model are fantastic.

5:41:04Jimmy and I are going very good as well.

5:41:07But we keep them as exception.

5:41:11So how do we get there?

5:41:14Some metrics that matter when you're self-hosting model.

5:41:18So to serve 2,000 engineers, we roughly need 56 B200.

5:41:23And that's to host GLM 5.3.

5:41:26GLM is a big model, right?

5:41:288.500 billion parameters.

5:41:31What you want to aim for is

5:41:33sub-3 second time to first token.

5:41:37This is empirical evidence.

5:41:38As soon as you exceed 5 seconds,

5:41:41my Slack inbox starts to blow up,

5:41:43and so we know that's the limit.

5:41:46In terms of throughput,

5:41:47it doesn't really matter as much.

5:41:48We serve, in terms of interactivity,

5:41:51200 tokens per second.

5:41:52People are fine.

5:41:53You don't need to go higher.

5:41:55The way people work has changed.

5:41:56which we no longer look at the stream of thinking tokens.

5:42:00People run tasks in parallel

5:42:01and check in when the task is done.

5:42:04But if you're in a high throughput

5:42:05and you're an engineer at Revolut,

5:42:07you just connect after 5 p.m. when one is on GPU

5:42:09you can get 800 TPS and then, you know, it's a dream.

5:42:15In terms of cost, in terms of impact,

5:42:17self-hosting, GLM, or blended cost of token

5:42:19is 30 cents per million.

5:42:22And so our invoice is one-tenth

5:42:24of what we were spending on Anthropic and OpenAI.

5:42:32So there's a lot of tuning

5:42:34that goes into running open source models.

5:42:38If you just get GPUs and upload weights on a GPU

5:42:43and you start doing some inference,

5:42:46you're going to get terrible performance.

5:42:47That's because your workload is going to be very dependent

5:42:51on the parameters that you set.

5:42:54So if you look all the way to the left of that chart, the blue line is going to be demand,

5:42:58so that's request per second.

5:42:59That's going to be what's going to be the bottleneck for your latency for your GPUs.

5:43:04And the red line is what we're optimizing for, that's the time to first token.

5:43:08So when we started back in April, you could see request per second around 3,

5:43:15which is high but not so high, and time to first token over 10 seconds, which is very slow.

5:43:21All of the data that you see is

5:43:23the same number of GPU. We did an increase GPU count with LLF56.

5:43:28And by the end, you see in August, requests per second were over 7, and time to first occur, and we're around 1.6.

5:43:35So we've had 88% improvement in performance for 76% increased demand.

5:43:43So the learning from this is there's a lot of parameters that you can improve on, and you really need to resist scaling.

5:43:48if you're looking to self-host a model.

5:43:52So let's talk parameters.

5:43:55There's no secret recipe,

5:43:56but the things you consider are the following.

5:44:01First one, long context is a scam.

5:44:04You really need to be mindful that

5:44:06even though you can serve one million token,

5:44:09256 is really what you need.

5:44:13Quantization, if you're running Blackwell generation GPU,

5:44:16you don't want to run anything higher than FP4.

5:44:19And the FP4 is best, roughly going from FP4 to FP8

5:44:24is a 40% saving in GPU footprint for zero loss in precision.

5:44:31Other parameters to consider, tensor parallelism,

5:44:34even though GLM fits on TP4, you don't have enough KV

5:44:38cache, and so maybe a TP8 works better,

5:44:40depending on how large your workload is.

5:44:43and then on the more esoteric

5:44:45check your cache hit

5:44:46coding test needs to be above 90%

5:44:49cache hit

5:44:51and you can look into optimize

5:44:53spec decoding

5:44:54sequential pre-fill, PD disaggregation

5:44:57all of these

5:45:00cool

5:45:01so now let's talk about production setup

5:45:04GLM obviously

5:45:05is a text only model

5:45:07which is a limitation for some people

5:45:09the trade off I would say

5:45:11we would make every time is get the smarter model and figure out how to do

5:45:14image recognition another way. You can easily have a local router, open codex is

5:45:20one, where you would route any image recognition to Gemini or Luna and keep

5:45:26GLM for the main task. If you really need some vision model, GLM 5G flash works

5:45:34really well. We have our UI designer making great use of it. Turnaround for UI product has gone a

5:45:44really, really long way. And then the last one is going to be about the harness. So all of these

5:45:52endpoints are going to be OpenAI compatible API with response API. And so you can use them

5:45:59inside OpenCode Codex, Codex app as well, works very well.

5:46:03And so that's what we recommend.

5:46:10And then last message, this one is for the CIO in the room.

5:46:16There's been a lot of stigma in using Chinese open source model.

5:46:21So the thing to consider is you're not using

5:46:24inference, dedicated endpoint that goes to China.

5:46:27you're just getting the weights and putting them on a US-based service.

5:46:32So for data sharing side, this is totally fine.

5:46:37Revolut in particular, because we're an EU-regulated bank,

5:46:41we fall under the most strict regime in terms of compliance.

5:46:46so what we find that works is all of these coding tasks are not considered autonomous agents.

5:46:53They're always with a human in the loop.

5:46:55And so how do you give reassurance

5:46:58that you have a human loop?

5:47:00You start by creating a sandbox that guarantees that.

5:47:04And the sandbox means now if you've used Codex Claude Code,

5:47:07it has all of these features of approve for me.

5:47:10You just have to set the rules for the operations

5:47:12that you don't want to allow.

5:47:13So you can allow grep but not gradle, for instance.

5:47:17And that's gonna give confidence to your regulator

5:47:19that it's not an autonomous agent

5:47:22that needs different supervision.

5:47:26This sandbox also protects you from rogue use.

5:47:29You may have bad actors inside your company, and you want to shield for that.

5:47:33You'd be surprised what you find in a large company.

5:47:37And then the last one is prompt injection.

5:47:39Not so much a thing now, given how smart models are, but always a thing.

5:47:45In terms of data privacy, we spoke about it.

5:47:47As long as the data sits in one of the countries that are in the data equivalency framework,

5:47:52so US, EU, UK, Israel, you're fine, you can get your GPUs there. All of your inference provider

5:48:00or GPU provider are going to have zero data retention by default. And then the last thing

5:48:07you need is a very strong open telemetry so that if you ever have an incident, you need to be able

5:48:14to go deep and look at the logs.

5:48:18Also gives you some analytics.

5:48:24All right, thanks everyone.

5:48:25That was all for my talk.