Machine transcription with reviewed terminology and names. Some recognition errors may remain. Timestamps refer to the livestream; subtitle downloads are timed to the session clips.
3:34:58Hello everyone, this talk is about the danger of your LLMZ formation leaking through shared
3:35:03GPU hardware.
3:35:04If you're running a model in the cloud on a GPU you share with other tenants, someone
3:35:08next to you can learn things about it.
3:35:10They can tell what model you're running, how fast it's responding, and even what kind
3:35:14work is doing right now, all without touching your data, just by watching timing. That's what
3:35:19this talk covers, what I quote tenets on the same hardware can learn about your LLM from timing alone
3:35:24and what you can do about it. To start, I'm Branislav Brzak, a cyber security researcher employed
3:35:31at Stealthium. At Stealthium we specialize in securing and providing observability into the environments
3:35:36AI systems run on. My area of focus is low-level GPU-related security research. That's something
3:35:42these stock covers. When you share a GPU between tenants, you would expect full isolation, but
3:35:49the isolation provided may not prove to be sufficient. In the case of this attack, the
3:35:54attacker doesn't even need any special permissions like root access. It doesn't need any traditional
3:35:59exploit either. The only thing it does is time the parts of the hardware that are still shared among
3:36:04tenants. This is a demonstration video of what the victims and the attackers dashboards look like.
3:36:10On the left, we have Qwen3 model doing inference.
3:36:14On the right, the attacker uses a side channel that Qwen3 leaks into as it's running.
3:36:19From that, it determines exactly what model it is and what kind of text it's producing right now.
3:36:27These are just the headline claims, but not the whole story.
3:36:30We can tell which model it is, architecture and depth, with the 97% accuracy.
3:36:35We can tell how fast is the coding, with the 99.3% accuracy.
3:36:39We can tell when and how much, the busy periods, token counts, and the answer length.
3:36:44What we can tell what kind of work it's doing, code, pros, JSON, or retrieval.
3:36:51What we cannot tell though are the actual prompt, answers, or contents, just timing.
3:36:57And all of this on real H100s serving real LLMs.
3:37:02If you're using NVIDIA hardware, GPU isolation is achieved using multi-instance GPU or MIG
3:37:07for short.
3:37:08Each isolated MIG slice has its own physical compute units and dedicated VRAM that provides
3:37:15hardware isolation on those parts.
3:37:17In our example, the LLM we are serving runs on a slice with 3 compute units and 40 GB
3:37:22of VRAM.
3:37:23The attack runs on just one compute unit and 10 GB of VRAM.
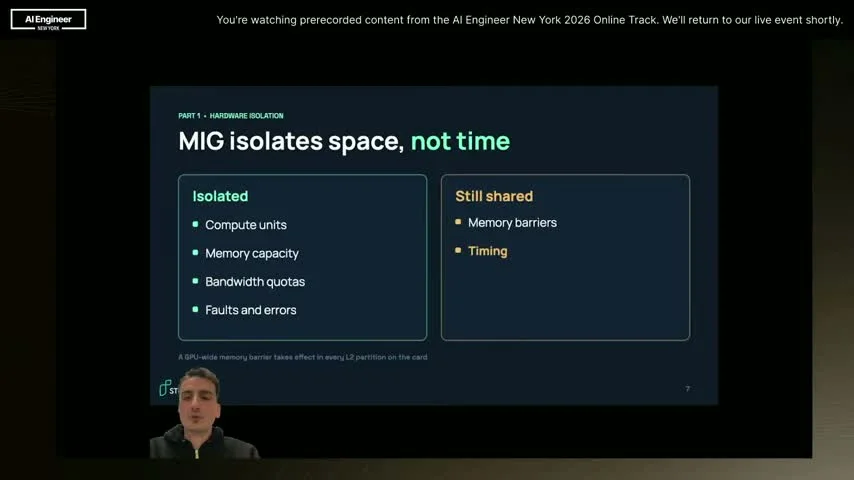
3:37:30What's isolated are compute units, memory capacity, bandwidth quotas, and faults and errors.
3:37:35The L2 cache is partitioned per instance too.
3:37:38There is no cross-instance eviction.
3:37:40So it's not shared in that sense.
3:37:42The actual leaks are memory barriers or members, which are GPU-wide.
3:37:47One instance's barrier still touches every L2 partition on the card.
3:37:52Timing is the one thing that isn't isolated.
3:37:55So when one tenant is busy, the other tenant's own reads get slightly slower.
3:37:59The key point is that a GPU-wide memory barrier takes effect in every L2 partition on the card.
3:38:07The next slide builds the whole attack on that one fact.
3:38:13The vector is that the attacker only ever reads its own memory.
3:38:18It only times its own reads, it never touches the victim's memory.
3:38:21There are three steps. Load from its own small buffer, time the load, and repeat every 5 microseconds.
3:38:26This primitive and the MIG member leak itself isn't our discovery.
3:38:31That goes to the researchers behind behind bars at using security.
3:38:37A big thanks for their work.
3:38:41Now try looking at the timing differences.
3:38:43With the naked eye comparing your tenant idle versus serving an LLM, you wouldn't even be able to discern them.
3:38:50The median latency is only 3 microseconds higher.
3:38:53To the attacker though, those 3 microseconds are all it needs.
3:38:57enough to gather all the information we already talked about.
3:39:03Qwen3 with 8 billion parameters is running on the victim's slides throughout this one.
3:39:08All captured data was taken from a live model.
3:39:11At the top is GPU activity over time, 1 burst per token.
3:39:15Below is the frequency spectrum of the attacker's own latency trace.
3:39:18There is a fundamental 881Hz which is just tokens per second plus harmonics, since each
3:39:24token is a mix of distinct frequencies, not one clean one.
3:39:30This is a real trace, one token in the time domain.
3:39:34The token shows a total of 39 bumps.
3:39:37bumps with green peaks are the layer invocations, while orange ones are additional between layer
3:39:43processing.
3:39:44In a later slide we will demonstrate how we determine the actual layer counts even though
3:39:50those extra bumps are present.
3:39:53we look at the decode speed itself.
3:39:55Just by timing we found the token rate completely bind.
3:39:58So speed alone is something an attacker can recover accurately.
3:40:03But speed by itself isn't a clean fingerprint.
3:40:06Qwen3 8 billion and Llama 3 8 billion decode only 1.6% apart in their token rate.
3:40:12So from speed alone you'd think they're the same model.
3:40:15It narrows things down but it doesn't nail it.
3:40:18We need something sharper, layer counts.
3:40:20That's what the next few slides get into.
3:40:24We use the same fold and average tick from before.
3:40:28This time we run it once per model instead of once per token.
3:40:31What comes out is a bit count that lands almost exactly on a whole number.
3:40:36The mean distance from an integer across 22 traces is just 0.028.
3:40:42That's the tell.
3:40:44If this were just a fixed hardware artifact divided by different token rates, it'd expect
3:40:49fractions, not whole numbers.
3:40:51Each count works out to the model's layer count plus 1 to 3 additional peaks.
3:41:00model keeps its own signal fingerprint.
3:41:03A mix of tempo and harmonic structure.
3:41:05To be clear, this is not a trained machine learning classifier.
3:41:08There's no training set, no labels, no configuration.
3:41:11It's under 30 lines of code.
3:41:13The method checks each candidate's depth from 16 to 48.
3:41:17It measures how strongly that depth's expected signature shows up in the real trace.
3:41:23Then it picks which are of its best.
3:41:25For Qwen3, 8 billion 36 layers wins Cleary by 4.0 times over the next candidate.
3:41:31Because this is a best fit test, not a lookup table,
3:41:34it also works on models it never seen before.
3:41:37That includes proprietary on unreleased ones,
3:41:40since there's nothing it needs to have seen in the first place.
3:41:48And this works surprisingly well.
3:41:51The layer fit classifier also outputs the confidence level.
3:41:55Across R testing, only two least confident answers
3:41:58ended up being wrong ones.
3:42:02This same method also picks up fine tunes and distillations that share the same base
3:42:08model.
3:42:09That's because the architecture and layer count carry over unchanged.
3:42:13Take three related models as an example.
3:42:17Llama 3 8 billion from meta has 32 layers.
3:42:20Llama 3.1 8 billion also from meta uses that same 32 layer backbone with minor upgrades.
3:42:26A R1 distilled Llama 8 billion from DeepSeek is an improvement on top of that.
3:42:32The per-layer timing comes out to only 1.6 nanosecond median latency shifts of each other.
3:42:40The rest of the signal looks the same.
3:42:42Regardless of this, our classifier is still able to discern between them.
3:42:47Now we ask a deeper question on the same channel.
3:42:50Not which model, but what is doing right now.
3:42:53We look at four workflow types.
3:42:55Prose, code, JSON, and retrieval.
3:42:57We give a workload on every half second based on the last five seconds of timing.
3:43:02Out of 40 half-second workloads 31 were right.
3:43:06And four full responses were correctly identified by majority votes.
3:43:12This is the same classifier from the video earlier misses included.
3:43:17One condition is worth stating.
3:43:19This was measured with speculative decoding turn-on.
3:43:22That's an opt-in in vLLM,
3:43:24not the default. Here's the mechanism. How predictable the text is changes how many drafted tokens get accepted at each step. That changes step time and that's the signal we're picking up. We tested 11 configurations, dense and mixture of experts, BF16 and FP8. The same figure page showed up every time, just at very different strengths.
3:43:4617.2% spread on GPT OSS 20 billion vs 0.9% on GLM-4-9B.
3:43:5310 out of 11 round pros fastest when the chance alone would only give you 1 in 4.
3:43:58So say the attacker already knows the model from the earlier slides and specular the recording
3:44:04happens to be on.
3:44:05It can also tell what kind of text is coming out.
3:44:09Now we take the Shadeship out of the picture entirely.
3:44:12MIG needs the attacker on the same physical die.
3:44:15This attack doesn't. The setup here is an 8x H100 server connected over an NVSwitch fabric.
3:44:24The victim runs tensor parallel across GPU 0 and 1. The attacker just needs any other GPU in that
3:44:31same server, GPU 2 in this case. Peer access over NVSwitch is a real intended feature. It's
3:44:37how multi-GPU jobs normally work, not a bug being abused. MIG tensor parallelism also can't coexist
3:44:45on the same device. So this is really a different population of deployments, not just the same
3:44:51attack repeated. The probe runs on GPU 2. It pointer traces memory that actually is on GPU 0
3:45:00over NVLink, timing every hop along the way. An idle hop takes about 890 nanoseconds. Once the
3:45:09victim starts working that climbs up to 300 microseconds.
3:45:13These are three half-second captures and you can actually count the tokens by eye.
3:45:21What we lose compared to MIG is the layer bit is below the noise at this
3:45:27distance. So over-enviling the fingerprints we
3:45:31were left with is mostly tempo, not layer count.
3:45:36Here we test the five models on identical serving setup. Only the model itself gives away which one it is.
3:45:43This method gives 79.2% accuracy. Now it fails exactly where you'd expect the tempo to fail.
3:45:51LAMA 3.58 billion and R1D Steel are both 8 billion models that they code 3Hz apart.
3:45:57So they blur together, where MIG's layer counts would have separated them easily.
3:46:02The takeaway is that the NVLink signal-to-noise ratio is worse than MIGs, since it loses the
3:46:09layer bit. But worse signal-to-noise ratio isn't the same as safety. 79% against the 20% baseline
3:46:16is still a real fingerprint, not noise. First, some good news. Our own product at work
3:46:24caught the attack straight out of the box. Stealthium monitors every single kernel launch
3:46:28across every GPU, analyzes suspicious workloads and runs them through a full alert pipeline,
3:46:34which is something not every vendor can do. Here is what made this one stand out. A single
3:46:40kernel relaunched about 3000 times, hitting the exact same 40 kilobytes of memory over and over
3:46:47instead of moving to new data. Only one kilowatt of data was sent back to the CPU the entire time
3:46:53because the timing itself was the payload, not the output.
3:46:57In real terms, that is under 600 milliseconds start to finish with fewer than 50 tokens over reply.
3:47:04We caught it before the response was ever half typed.
3:47:11So, three takeaways.
3:47:13First, placement is something operators actually control.
3:47:16So do not put an untrusted tenant's MIG slice right next to sensitive model.
3:47:21Second, know the trade-off.
3:47:24MIG rules out peer-to-peer communication, meaning there is no tensor parallelism on
3:47:29MIG.
3:47:29Sharding over NVLink instead limits what leaks to timing alone rather than the layer accounts.
3:47:36Third, watch the GPU itself.
3:47:39Make sure the host infrastructure is actively verifying that no malicious workloads are running
3:47:45on the hardware.
3:47:46That's exactly what Stealthium does by catching these probes straight from the Chrome behavior.
3:47:53Sharing a GPU means timing alone can give away the model, the speed, and the workload.
3:47:59That's true even across NVLink, without needing any export at all.
3:48:04Stealthium sees this happen in real time. Most organizations still don't have that kind of visibility.
3:48:09Thanks again to the researchers of Behind Bars, this whole talk builds upon their work.
3:48:15Thank you all for watching.