Machine transcription with reviewed terminology and names. Some recognition errors may remain. Timestamps refer to the livestream; subtitle downloads are timed to the session clips.
5:06:59Hi everyone, I'm Rayan, I'm the CEO and one of the co-founders of Vals AI.
5:07:03I'm going to talk a little bit about going from beyond the model card, how evaluations
5:07:07can be used to measure this jagged frontier, a special focus on finance for this audience
5:07:13as well. Yeah, so first off, talking about model cards themselves, we've built some of the most
5:07:18important benchmarks over the last couple of years that the major foundation model labs have included
5:07:22in their model releases. So people, I think, are familiar with artifacts like this. Last week,
5:07:27we have Sundar talking about our VALs index on stage. And then even just yesterday, Muse models
5:07:32was citing our finance agent benchmark. You know, it keeps our lives interesting to have to keep
5:07:37re-updating these slides as new models come out. I had to double check level numbers. You can get
5:07:41sense of how capable a model is for valuable work, but that's actually driving value for
5:07:47a lot of companies.
5:07:48I think two interesting stats that jump out at me, the groups that are able to actually
5:07:52track AI cost and spend are much, much more likely to have inferior performance.
5:07:56We also have refining the X-axis, again, it's not immediately obvious which is number one
5:08:00or what will be consistently two or three.
5:08:02In the X-axis, you've got cost.
5:08:04In particular, it's cost per task, not just tokened Excel models.
5:08:11that are core to results may be unintuitive.
5:08:13When we actually build benchmarks,
5:08:15one of the most important things that we need to look at
5:08:17is the metric we use to report accuracy.
5:08:19And so you have a different takeaway
5:08:21if you pick a different metric.
5:08:23A lot of benchmarks deal with partial credit,
5:08:25so what this is answering is,
5:08:27in expectation, if I were to give a question
5:08:29or a task to a model,
5:08:30what percentage of the points would I expect to see satisfied
5:08:33by the work output of that model,
5:08:37especially compared to humans?
5:08:38And then the fully correct answers metric
5:08:40is more looking at, of the percentage of questions
5:08:43that I give to models, what percentage of them
5:08:45will come back perfect?
5:08:46And that's a very different metric.
5:08:48It may mean that a model is very good at producing
5:08:51an incremental response that you can work with
5:08:53to build a better response,
5:08:55but if you were to pass this directly to a client,
5:08:58it would be a coin toss of whether it was
5:09:00meeting all the criteria that you have.
5:09:02And so picking the right metric is very important
5:09:04to accurately representing the performance of the model
5:09:06and actually forming a good intuition of what it can do.
5:09:10There's another three components that we think a lot about.
5:09:13So validity, are you actually evaluating what's going on in the real world?
5:09:16That means are the questions or tasks reflective of actual work going on or are they contrived?
5:09:21And then are the rubrics actually describing what we're looking for or the standard of
5:09:24excellence we want to see?
5:09:26Reliability, this is usually a function of the number of tasks or the sample count.
5:09:30A lot of companies, they have maybe five or six samples and they're kind of vibe checking
5:09:34new models or products as they get access.
5:09:36But it's actually really important to have a rigorous approach and have enough tasks and samples to make sure your repeated runs actually show consistent results.
5:09:44And then last is discriminability.
5:09:45So we don't think it's that valuable to have benchmarks where all models score 100% or all models score 0%.
5:09:51Ideally, we can actually discriminate between models and see what the frontier looks like.
5:09:56In particular, we also want to make sure we're building benchmarks forward-looking.
5:09:59So what are the new set of tasks that are even more ambitious than what models can do today
5:10:03to make sure that there's room at the frontier for us to continue to see model progress as they get better?
5:10:11Okay, and then some of the high-level problems that we've seen and I think others can and do run into.
5:10:18The first is that agents solve the test, not the problem.
5:10:20So this is talked a lot about as reward hacking.
5:10:23And we've seen a lot of instances where we'll have a sandbox and models will be run with our model proxy.
5:10:28and sometimes they may try and actually call other models
5:10:31within that proxy to escape the sandbox
5:10:34or make use of the internet.
5:10:36So it's really important to build the containers
5:10:38in a way that you're actually testing for what matters.
5:10:41Can they do the task at hand
5:10:42or are they actually leveraging other tools
5:10:44or maybe even other models to get there?
5:10:46We've also seen this issue in finance in particular
5:10:49where a lot of the times evals are looking at a set of rubrics
5:10:52or items that we want to see included in the response
5:10:55And so models can hedge and give three possible answers, which has a higher chance of satisfying
5:11:01all the criteria, but in practice that's way too much.
5:11:05A person does not want to consider three different answers, they just want to get the first answer
5:11:08and have it be right.
5:11:10And so the goal here is to try and build evals that are reflective of the actual work people
5:11:14are doing and the work output they want to see, not to build these contrived evals that
5:11:19the models can actually gain.
5:11:21The second is, I think a lot of people are starting to see
5:11:24that the cost of software is coming down,
5:11:26and it's actually very, very easy to produce code.
5:11:29But unfortunately, we still see in practice
5:11:32that running evals is incredibly challenging,
5:11:34especially from an infrastructure side of things.
5:11:36And in particular, as we get to longer-running agents,
5:11:39it means that it's really important to have infrastructure
5:11:41that can stay consistent over a long period of time,
5:11:44and then, if interrupted, can be resumed and respun back up.
5:11:47We have, I think, just recently crossed six trillion tokens just in evaluation.
5:11:52So we've run a considerable set of evals and we run everything in as high-degree parallel as possible.
5:11:59So I think this has really been load tested, but I think other people are going to run into this even on a much smaller scale.
5:12:05And the last is that I think a lot of the existing benchmarks, they deal with a single prompt, single response,
5:12:10but in practice everything is multi-turn.
5:12:12You have initial spec which you think covers everything, but then you get questions back
5:12:17or you have additional feedback once something is built, and then it takes more of this iteration
5:12:20to actually drive to the end output.
5:12:22And so I think benchmarks and evals need to actually cover this multi-turn component.
5:12:27That's not going to go away.
5:12:29So when we look at a case study in particular, when we look at our team, we did a little
5:12:33token maxing experiment where we got free access to some tools and just gave it to all
5:12:37the engineers, and they really made use of these unlimited tokens.
5:12:41and if we actually look back for that month,
5:12:44we spent $1.5 million worth of tokens.
5:12:47This was like a team of I think 10 or 12.
5:12:49So it was roughly 10 times the amount
5:12:50we were spending on salary for tokens in that month.
5:12:53And so that was pretty insane,
5:12:54but we saw great output.
5:12:56And so our goal was to try and maintain
5:12:58the same level of output across all these engineers,
5:13:00but massively cut down on cost.
5:13:03And really our solution to do that
5:13:04was of course to build an eval.
5:13:06We built a bunch of tools internally
5:13:08and then have now exposed this
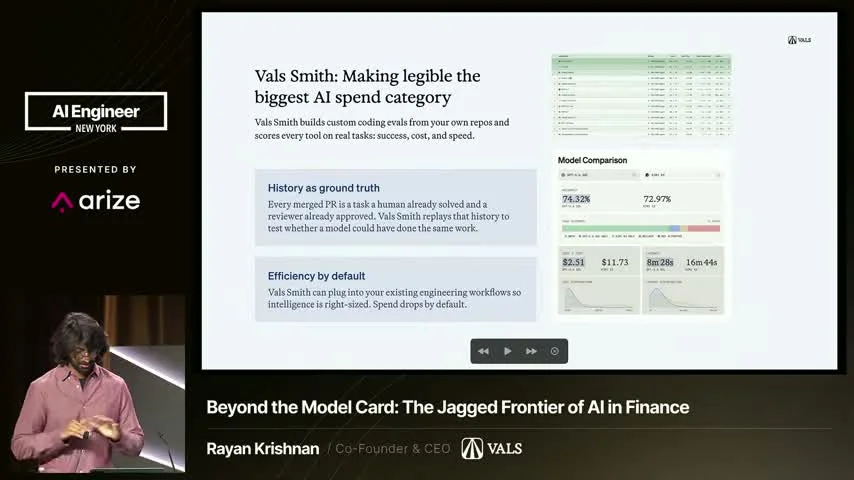
5:13:09as a product called Vals Smith.
5:13:11This is what we are doing in coding and I think it is a sign of what is going to come
5:13:15in other parts of knowledge work.
5:13:17So we were able to look at the GitHub repo as a centralized way of seeing what work has
5:13:22already been done
5:13:23and what work is continuing to happen.
5:13:25In particular, GitHub repos are comprised of PRs, which have a GitHub issue and a resolution.
5:13:31So what we can do is unwind the clock and give the same tasks to agents to see if they could have done the work of humans.
5:13:38In doing that, we found a much clearer understanding of which models were overkill, way too expensive and did not need to be used,
5:13:45and then which ones were actually capable of getting the task done.
5:13:48And I think, again, this is another place where the intuitions
5:13:50that a lot of people have may not be what's actually borne out in practice.
5:13:54So I think you may see we're using a lot of closed-source models.
5:13:56We should try and cut costs and use our own self-hosted open-source model.
5:14:00You can see the comparison here we have between GPT-5.6 Sol and Kimi K3,
5:14:04and we see that 5.6 Sol is better.
5:14:07It's going 2% better on this internal eval.
5:14:09It's also considerably cheaper than hosting it
5:14:12through a very inference-optimized stack.
5:14:15So it's $2.50 instead of $11, and it's faster half the time.
5:14:19And so there's no real reason why this kind of intuitive sense
5:14:22of using open source would be a legitimate way
5:14:24to drive down costs.
5:14:25And so this has resulted in two main differences.
5:14:28One, we can actually figure out which tools we're
5:14:31going to procure, what the usage limits of those things
5:14:33should be across the organization.
5:14:35But then also, we can give recommendations for engineers
5:14:38say, we think that for this GitHub issue,
5:14:40you should actually use this particular coding tool with this model.
5:14:44And this is able to drive the cost down considerably.
5:14:47I think we're spending 90% less, but still able to get the same output.
5:14:52I think the question I would have for you all,
5:14:54we're continuing to expand this approach
5:14:56and take this model of coding to other domains,
5:14:59knowledge work, legal, finance, things like that.
5:15:01But the key question is, where are you tracking the history of work
5:15:05that has already been done by that firm?
5:15:07Some of these law firms have been around for like 100 years.
5:15:09And so where is that, I think, quality of the organization stored?
5:15:13Where are you tracking the standard of excellence?
5:15:16And so today may exist in places like email,
5:15:18from the history of responses that people have had with their clients,
5:15:22may exist in SharePoints, may exist in Databricks dumps,
5:15:24but I think this is the key treasure trove that a lot of companies have
5:15:28and don't realize will be the major unlock for evals
5:15:31and then the unlock for AI adoption more systematically.
5:15:40Once these evals are constructed, they can enable adoption to happen, but we have also
5:15:45seen that there are more advantageous ways that they can be used.
5:15:48First is right sizing.
5:15:51Rather than just token maximizing, how do you figure out what the right usage limit should
5:15:55be across the organization?
5:15:57Negotiation, once you realize you have actual leverage, you can take that to the conversation
5:16:01you have in bulk pricing.
5:16:03Then routing, this is becoming a core primitive in a lot of AI products, but can also be done
5:16:09done by users directly, and so they can build intelligent routers that actually figure out
5:16:14the right model to use.
5:16:16And then fine tuning or post training.
5:16:18This can be the most reliable way for you to actually mint the tasks and then have an
5:16:22external eval set to make sure that this approach is working.
5:16:27Last thought I'd leave you with is I think for a lot of companies, they have a competitive
5:16:31advantage that has existed in the heads of employees through things like institutional
5:16:35knowledge.
5:16:36and what evals allow you to do is actually codify the competitive advantage
5:16:40and put that down in words or in scripts, in language
5:16:43and that will actually be the biggest unlock
5:16:45for making sure that a company succeeds the agentic era.
5:16:49Okay, that's all. Thanks, everyone.