Machine transcription with reviewed terminology and names. Some recognition errors may remain. Timestamps refer to the livestream; subtitle downloads are timed to the session clips.
1:28:45My name is Freddy Lecue.
1:28:47I'm part of the Wells Fargo team.
1:28:49I'm leading the Frontier AI modeling organization here.
1:28:52And I'm going to show you the work we've been doing lastly on building our first foundation
1:28:58model, Wells Fargo Foundation model.
1:29:01So I explain why we did that, how we did it, and what we accomplished.
1:29:05in doing so so so first from financial model it doesn't necessarily need to be language based i
1:29:12mean we're all playing with uh claude and chat gpt and others they're all language-based
1:29:18from the show models in financial services uh we also have language of course uh from a
1:29:24structure unstructured representation data but we also have a lot of structure representation
1:29:29a lot of these data is tabular data we have a lot of information from our customers we have
1:29:34information in investment banking, consumer banking, and all of this data is data that we
1:29:40have in Wells Fargo, and all big financial organizations have too. And we want to take
1:29:47benefit of all of this huge amount of data that we have. And it's not like you just take it and
1:29:53put it in a language model and get the best of it. Of course, you can get a lot of benefit out of it,
1:30:00but it's not necessarily the best way to do it.
1:30:03So what we decided to do is to look at the data we have,
1:30:07all the transactions, all the customer transactions
1:30:10that they're doing with their debit card, credit card, digital, check,
1:30:13all of those coming from many different channels
1:30:16and see if we can build a foundational model
1:30:20that we can use and fine-tune for downstream tasks
1:30:23like credit scoring or that you can use it for fraud detection,
1:30:27anti-money laundering, do marketing.
1:30:28So how we can build one backbone that you can use and streamline across downstream tasks.
1:30:35So now you're moving from many models very siloed across different organizations.
1:30:41In really one backbone that every organization can just reuse because you learn the representations of customers' transactions at scale.
1:30:51So that's the intent.
1:30:52And just spoiler alert, you may say, hey, that's tabular data.
1:30:55why do you just don't use XGBoost and the usual suspect?
1:30:58We did that.
1:30:59This is the model we had in production.
1:31:01But the model I'm going to show you is something that beats XGBoost,
1:31:06even from a latency perspective, but also from a fault detection,
1:31:11we get much better reduction of false positive and better detection rate.
1:31:17So it was a really good lesson learned in terms of having better model
1:31:23using foundation model.
1:31:24And to foundation, I mean transformer blocks, and that's what we build.
1:31:30So we have, as I mentioned, billions of transactions on a monthly basis.
1:31:36Our customers are interacting with their debit credit card, and they do checks, and they do different sort of transactions.
1:31:42And the question is really how we can use this information at scale, and not for one and every single downstream task.
1:31:50So I'm going to cover a bit of the data, the representations, the architecture that we use,
1:31:58what the result we get, and the lesson we learned in building this.
1:32:04So left-hand side, language foundational model.
1:32:07They're processing language tokens, and then the goal is to learn the representations that's going to predict the next token.
1:32:14and then you have supervised fine-tuning
1:32:18and then you do LHF, LRVR
1:32:20and all of the great post-training process
1:32:24to get better at the task that you want to, right?
1:32:27And that's for languages, that's great.
1:32:29But what if your data is very much more specialized
1:32:33in terms of representation?
1:32:35So that's where we build this transaction foundation model.
1:32:39So instead of having languages as the base,
1:32:42the base is now transactions.
1:32:45transaction from our customers.
1:32:47And you still try to predict the next thing,
1:32:49and here the next thing is the next transaction,
1:32:52or it's the next token in the transaction,
1:32:54using all of the channels that you have.
1:32:56But that's not the end goal.
1:32:58I mean, similarly to language model,
1:33:00where you try to predict the next token,
1:33:01that's not the end of the story, right?
1:33:03You learn the representation,
1:33:05and then you use that representation,
1:33:06and then you fine-tune it,
1:33:09and you post-tune it for any other task, right?
1:33:12So it could be classification tasks for languages,
1:33:14but in our context for transaction foundation model it could be used for
1:33:18credit line increase could be used for doing fraud detections and flagging
1:33:22bad actors from
1:33:23an anti-money-laundering perspective.
1:33:25And the goal is to learn this relationship between transactions over time and transactions across customers. That's really the intent.
1:33:34So the intent number one is you do pre-train from scratch. I'm saying it again because people are sometimes confused.
1:33:41we pre-train transformer blocks at scale from scratch using our transaction data.
1:33:49So the zero rate that we use from open rates, we just use the architecture,
1:33:54and then we pre-train it from scratch using our GPU cluster,
1:33:58and then we train it for a couple of days and weeks,
1:34:02and then you do the downstream task of post-training.
1:34:06but the goal here and you pre-train it
1:34:08for predicting the next
1:34:10token or the next transactions
1:34:12and you try to do this
1:34:14you try to predict the next pattern
1:34:16of the customer but that's not the intent
1:34:18the intent is to do the downstream
1:34:20task later on and in terms of scale
1:34:23we operate
1:34:25at a large scale
1:34:26so we have billions of transactions
1:34:28a million of accounts
1:34:30hundreds of transactions
1:34:32per client on a monthly
1:34:34basis interacting with their
1:34:36debit card, credit card, or doing check.
1:34:39And the five main dimensions we look at
1:34:42is really who is doing,
1:34:44I mean, who is processing and who is asking
1:34:47and who is providing a service.
1:34:49So, will it the customer or the merchant?
1:34:52The what?
1:34:53So, I mean, what do we buy?
1:34:56What do we transact?
1:34:58And how?
1:34:58So, which channel?
1:34:59Is it credit?
1:35:00Is it debit?
1:35:00Is it digital?
1:35:02When is it happening?
1:35:03And where is it happening?
1:35:04And all of those, they're basically breaking down in hundreds of features.
1:35:08And if you look at the existing model we have in production,
1:35:12there's a lot of people that build those models in similar organizations
1:35:18may understand that.
1:35:20They build a lot of very hard-crafted, uncrafted engineering,
1:35:24feature engineering efforts on that.
1:35:26And that's required a lot and a lot of time.
1:35:28So we step back and look at the raw features we need,
1:35:32not the one that's been pre-built and post-built for doing the downstream tasks,
1:35:38but try to understand which raw features.
1:35:40And we ended up with basically Android features.
1:35:43Even at the end of the day, we had thousands of them,
1:35:46but we tried to find which ones are the raw information unit.
1:35:51And then we led the architecture, the transformer blocks,
1:35:55to figure out the relationship between those core features.
1:35:57and as you can see
1:36:00we do have a bunch of features
1:36:03on those five dimensions
1:36:05and the vocabulary is very unique
1:36:07to the financial services setup
1:36:10and that's the reason why
1:36:13we didn't really use
1:36:15existing pre-trained model
1:36:17because the vocabulary that we use
1:36:20is very specific to the work
1:36:22that you want to do
1:36:23and even if you merge
1:36:26while all digital and checking and saving
1:36:30and all of those sort of transactions,
1:36:34even if you merge all of those,
1:36:35you still end up with a very limited number of features and characteristics.
1:36:39So at that scale, then the question is,
1:36:42well, how you work with that?
1:36:44So we started, everything is tabular data.
1:36:46I mean, there's no secret, it's tabular data.
1:36:48And then the goal is to understand
1:36:50how you're going to capture the vocabulary
1:36:53because you do have numerical values,
1:36:55you have categorical values, you have information like zip code,
1:37:00do you encode each and every zip code in a token?
1:37:03Does it make sense?
1:37:04So there's a lot of efforts you need to push in understanding
1:37:08the vocabulary that you need and the vocabulary that you want also to scale
1:37:13because at the training, if you have too huge vocabulary,
1:37:15it would be kind of messy to train such a model with a vocabulary
1:37:20which is far, far too big.
1:37:21So there's a lot of effort in understanding this value to tokens.
1:37:25So which information do you encode in a token?
1:37:28And then you have the token to ID, the tokenizations,
1:37:31and then the embedding lookup.
1:37:32So then when we have a transaction coming up,
1:37:35you do have the vocabulary.
1:37:36So basically it's a lookup in aligning a transaction
1:37:40and all the characteristics of that transaction
1:37:42to a token and an ID and then an embedding.
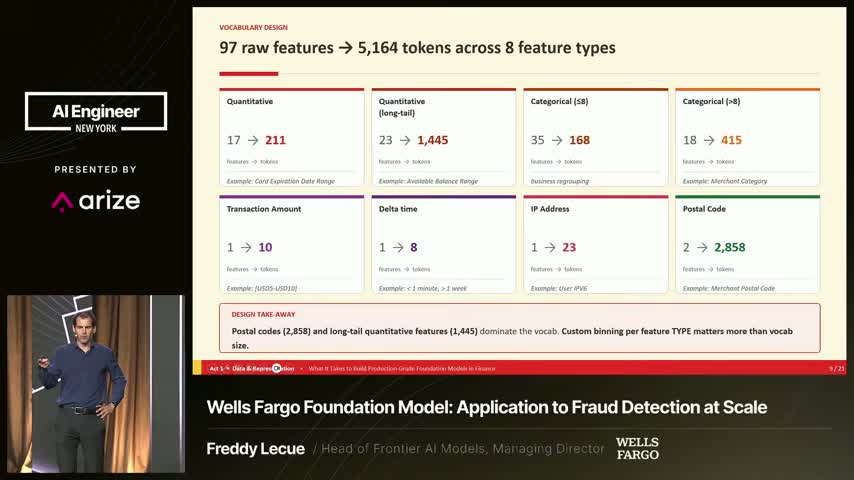
1:37:48So just to give you a number,
1:37:50well some numbers so we have quantitative qualitative categorical of different kind
1:37:56right so categories with only eight types some with much bigger types you have transaction amount
1:38:02which is a big deal you have the delta time between transaction so you have anything related
1:38:08to ip address postal code so just to give you example of variety and heterogeneity of each and
1:38:15every characteristic could be encoded in a binary token
1:38:19or could be encoded in a much larger number of tokens.
1:38:23And even if you look at the zip code,
1:38:25I mean, you have a much larger number of zip code
1:38:27in the US than those 2,800,
1:38:31but you have much better way to structure
1:38:35how you're going to regroup zip code
1:38:38based on distributions, for instance.
1:38:40so architecture
1:38:43so here just
1:38:44so we use the
1:38:47chinchilla
1:38:49mathematics behind
1:38:50to define how we build it
1:38:53initially because we had
1:38:55no clue how it's going to work in the tabular
1:38:57space even though there are
1:38:59existing
1:39:01open ways and open solutions
1:39:03for doing tabular
1:39:05data foundation models
1:39:06so we started from
1:39:09what they learn and adapt it to what we needed to do and that gives you an
1:39:13example of invading dimensions number of decoder blocks we use and all of the
1:39:18recipe from a from an architecture perspective so we have and as you can
1:39:24see we're not trying to build a trillion parameters model we don't try to compete
1:39:29with any of the the leaders in the language models because we working with
1:39:35and focusing on transactions, right?
1:39:38Transactions, foundation models at billion level.
1:39:41And one billion is because that's the model that gave us,
1:39:45that was kind of the smallest and gave us the highest boost.
1:39:49And now we're working on the next versions at 11 billion.
1:39:52But that's good enough to give a lot of ROI
1:39:56from a false positive reduction for downstream tasks
1:40:00like for detections and the detection,
1:40:03unit detection rate.
1:40:05So, and the type of architecture,
1:40:09so the decoder-only architecture,
1:40:10that's basically for predicting the next token
1:40:13or the next transactions.
1:40:15And that's really the pre-training.
1:40:17So here we initially used 20 times the number of parameters
1:40:20to define the number of tokens we might need.
1:40:23We ended up actually 10 times fractured than that.
1:40:26So by doing a few experimentations,
1:40:28we needed much more tokens per parameters.
1:40:32I mean, this is kind of the initial experimentation we did.
1:40:37So I'll pass on this because this is the usual suspect
1:40:40from an objective function,
1:40:43so causal language modeling and mass language modeling
1:40:46type of optimization work.
1:40:51And from an architecture perspective,
1:40:54nothing really fancy here.
1:40:57the most complex part was really the tokenization
1:41:00and then
1:41:01doing the pre-training and then how you do the fine-tuning.
1:41:04So I would say the recipe or the secret sauce
1:41:07is really how you do the tokenization
1:41:09and how you're going to do the post-training.
1:41:12But anything from a training perspective,
1:41:15the question is just
1:41:17how many transactions
1:41:19you're going to put in your context
1:41:21or in your history for doing the training.
1:41:24and evaluation perplexity-based accuracy dashboard
1:41:28on downstream tasks.
1:41:30That's the ULs respect.
1:41:32And so, yeah, so use mixed precision,
1:41:36distributed data parallel,
1:41:39maximize macro batch size,
1:41:42get faster convergence,
1:41:44yeah, using Muran,
1:41:47Rope, usual,
1:41:48and memory efficiency, flash attention,
1:41:51activation chain pointing.
1:41:52I mean, here there's nothing really new.
1:41:54It's just we use the advices from the best
1:41:59and from the one that built even much bigger models.
1:42:03So I'll pass on this one.
1:42:05Time is short.
1:42:06But I wanted to spend some time on the results.
1:42:11So, yeah, so when you build this foundation,
1:42:16That foundation is really, is only a backbone.
1:42:22It's something you can use for downstream tasks.
1:42:24And the downstream task was to do fraud classification.
1:42:28So you have a transaction, and then you try to predict if that transaction is going to be fraudulent.
1:42:33So in the model we have in production, it's an XGBoost model,
1:42:37and it's trained on large amount of transactions, which is fraudulent or non-fraudulent.
1:42:42and the missing pieces
1:42:44was the relationship
1:42:47between whatever transaction
1:42:49you try to predict, try to classify
1:42:51and the relationship with this
1:42:53transaction with all of the past transactions
1:42:55and that information is kind of
1:42:57gone when you use an XGBoost model
1:42:59unless you encode it
1:43:01in a very hard way which is not
1:43:03so easy but if you use
1:43:05transformer architectures you do have
1:43:07these nice attentions
1:43:09from transactions to
1:43:11past transactions
1:43:12And that's basically what helps, and this is what we think, this is what really helps pushing the fraud detection rate much higher.
1:43:20But at the end of the day, the downstream task was to say, here's the
1:43:23sequence of transactions. I have someone just using the debit card. Is that transaction fraudulent with respect of all historical information? And that's exactly what you put in at inference time when you try to do the prediction.
1:43:39so that's the
1:43:43architecture so nothing
1:43:44really fancier you just need to have the
1:43:46good engineering
1:43:48in place to do
1:43:49less than 250
1:43:52milliseconds for doing the processing
1:43:55because the
1:43:56decline needed to happen within that time frame
1:43:58but it's
1:44:00we were
1:44:0110 times slower than done from a latency perspective
1:44:04so it was all good
1:44:05and just in terms of
1:44:08final result we get. So the main
1:44:10metrics and those metrics
1:44:12relate right away to
1:44:17savings for the firm.
1:44:18So it's detection rate
1:44:20and false positive rate. Of course
1:44:22you can detect much higher, but
1:44:24in many cases
1:44:26sometimes you get much more false positive.
1:44:28And in this case, we managed to get
1:44:30more fraudulent
1:44:32activities and we even
1:44:34reduced the false positive.
1:44:35so that was a big win
1:44:37because at the end of the day
1:44:39if you decline a transaction
1:44:41which is not fraudulent
1:44:42then that person is going to call
1:44:45there is an operation cost associated to it
1:44:47you lose the transaction related to
1:44:49that non-fraudulent action
1:44:51so it's a very
1:44:54well
1:44:55something that you don't really want to happen
1:44:57so again
1:44:59that's compared to the state of the art
1:45:02of the XGBoost model
1:45:03using fraud detection
1:45:05So it's basically huge.
1:45:08It's millions of dollars savings.
1:45:11So it's a very big boost.
1:45:13So just to finish up on that slide,
1:45:17so that foundation model has been built on billions of transactions
1:45:24from Wells Fargo customers.
1:45:27That's number one.
1:45:30It's pre-trained from scratch.
1:45:32So we don't free train from any open-rate existing model.
1:45:35We use existing architecture, but the way the zero rate, we pre-training on a couple
1:45:40of days.
1:45:41I mean, we did a couple of weeks initially, but then that's pre-trained.
1:45:45And then when it's pre-trained, it's pretty good in predicting the next transaction.
1:45:49And when you're done with that, then you can use it for many downstream tasks.
1:45:53We did it for fraud detection.
1:45:54Now we're investigating for credit line increase, investigating for anti-money laundering,
1:45:59investigating for marketing.
1:46:00so now the same foundation is used
1:46:03across different organizations
1:46:05even Wells Fargo
1:46:07and yeah
1:46:08thank you for having me and thank you