Vector databases and enterprise AI knowledge infrastructure
Pinecone
Pinecone builds infrastructure that connects AI applications to their own data. Its fully managed vector database supports search, recommendations and agents, storing vectors and retrieving relevant records without requiring developers to manage database servers. Its broader platform includes Pinecone Nexus, which compiles enterprise data into structured knowledge for agents, and Pinecone Marketplace, which offers production-ready knowledge applications.
Pinecone was founded in 2019 by Edo Liberty, previously a research director at AWS and Yahoo. Working on large-scale vector search for applications such as spam detection and recommendations, Liberty saw a gap between what well-resourced research teams could build and what other engineering teams could readily use. Pinecone’s founding aim was to package that storage and retrieval infrastructure as a managed service accessible to teams with different levels of AI expertise. Liberty now serves as founder and chief scientist; Ash Ashutosh is CEO.
The database’s object-storage architecture separates stored data from the machines that process queries, allowing storage and compute to scale independently. Writes first enter a persistent log, then become searchable through an in-memory structure before being organized into immutable sets of files called slabs. Each slab contains vectors, metadata and search indexes. Background compaction merges smaller slabs into larger ones, and Pinecone chooses indexing algorithms for each slab automatically. Searches run across slabs in parallel, with a query router combining their results. Developers can use elastic, usage-priced On-Demand infrastructure for variable traffic or reserve Dedicated Read Nodes, priced by shards and replicas, for sustained query workloads.
With Pinecone Nexus, the company extends retrieval infrastructure into a knowledge layer shaped by subject matter experts. An expert defines a manifest describing the entities, relationships and answer structure a particular job requires. Nexus then curates documents, databases and other connected sources against that structure, producing reusable knowledge and a relationship graph. Agents query it through KnowQL, specifying the question, output shape and scope in one call. Responses include typed fields, per-field citations, confidence scores and access controls. Curation and querying run in the customer’s cloud using their chosen models, with no standing Pinecone access to the data.
Nexus became generally available on August 6, 2026. Its approach moves some knowledge preparation ahead of the agent’s query: domain experts shape a reusable layer instead of leaving an agent to repeatedly retrieve and assemble raw material on every call. This also broadens Pinecone’s intended users beyond developers to professionals such as analysts, underwriters and attorneys who understand the work the agent must perform. In the same announcement, Pinecone reported serving more than 10,000 customers and one million developers worldwide.
Explore the recordings
Pinecone’s supplied archive contains one recording: Pinecone 2.0 — Edo Liberty. The paths below approach that talk through different questions. Product descriptions, results and launch statements reflect the recording; they do not establish current availability or performance.
What does an enterprise agent need to know?
Start with Liberty’s distinction between general, specific and tribal knowledge. His theory-of-mind framing and Yahoo Answers anecdote introduce the gap between what users assume a system knows and what it can access. This path is useful for thinking about organizational understanding beyond document retrieval, including processes, priorities and decisions.
Designing a persistent knowledge layer
Follow the talk’s proposed shared knowledge layer and Nexus presentation for an architecture-oriented path. Liberty describes domain specialization, expert ownership and freshness, then connects these concerns to connectors, contexts, tasks and declarative manifests. His presentation combines semantic maps, Markdown notes, SQL tables, vector indexes and graphs, with import and curation used to assimilate information.
Query budgets, runtime code and reported results
Use the NoQL and runtime coding-agent discussion to explore how the proposed layer answers agent queries. Liberty describes token, dollar and time budgets, structured grounded output, and code written, executed and revised at query time. He reports a tooling-prompt reduction from roughly 150,000 tokens to fewer than 1,000, plus early-access efficiency and qualitative accuracy gains. The supplied summary provides no detailed evaluation methodology, so treat these as speaker-reported results. His public-preview announcement for “tomorrow” establishes neither a calendar launch date nor today’s product status.
1 talk
Newest first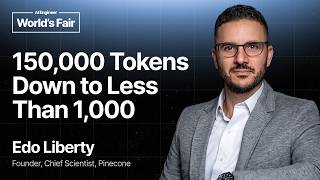
1 speaker at AIE
Affiliations reflect their AIE appearances, not necessarily current employment.