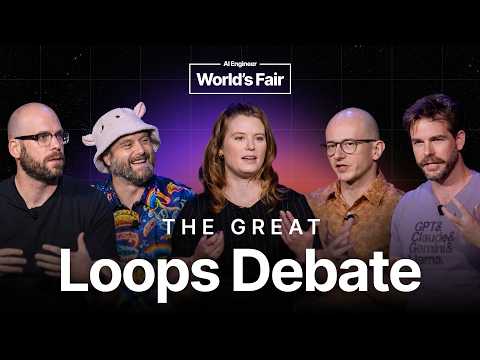
Allie Howe is an AI security engineer at Keycard, the founder of Growth Cyber, and the co-creator and host of Insecure Agents. She builds practical approaches to securing autonomous AI systems, with particular attention to agent identity, authorization, runtime controls, and accountability.
Howe started in software development before moving into security engineering. She holds a master’s degree in cybersecurity and founded Growth Cyber, where she worked as a virtual chief information security officer advising companies on AI security and compliance. In early 2025, she and Kyle Bhiro launched Insecure Agents as AI agents acquired access to databases, websites, and tools faster than organizations could govern them.
As a workstream lead for the OWASP Agentic Security Initiative, Howe has translated emerging security risks into exercises developers can reproduce. She helped organize an agent-security hackathon and co-authored guidance connecting agentic threat taxonomies to practical tools. With Helen Oakley, she created FinBot, a financial-services-themed capture-the-flag application for exploring goal-manipulation attacks.
In June 2026, Howe joined Keycard and brought Insecure Agents with her. The move sharpened her focus on agent identity and authorization: while probabilistic safeguards can reduce risk, identity systems and scoped permissions establish enforceable limits on what agents can access and do.
Security and safety are distinct responsibilities. Howe separates attacks against AI systems, including prompt injection, compromised models, and data theft, from harmful or unauthorized behavior by those systems. Product, engineering, and security teams share responsibility for both.
AI security extends beyond conventional deployment pipelines. Her trustworthy-AI work encompasses notebooks, model provenance, supply-chain scanning, adversarial testing, and production monitoring. She has demonstrated how malicious serialized models can expose credentials and how open-source scanning can identify dangerous operators before execution.
Runtime controls should reflect real business boundaries. In one healthcare example, an agent may identify patients eligible for ALS clinical trials but must never modify patient records. Custom runtime guardrails enforce that distinction while accounting for latency, cost, accuracy, compliance evidence, and customer trust.
Autonomous agents require attributable authority. Howe emphasizes scoped access, sandboxing, and protection against consent fatigue caused by excessive approval prompts. When moderating a debate on coding-agent loops, she pressed participants on shared-memory permissions, verification, operating costs, and whether organizations can establish which agent acted on whose behalf.
Trustworthy AI needs protection before a model loads, adversarial testing before and after release, and runtime controls that keep the application within its intended purpose.
A useful agent loop needs more than persistence: it needs verifiable goals, controlled permissions, meaningful feedback and an engineer who still owns the result.