Karina Nguyen is the founder of Thoughtful, an AI product-research company developing more capable, trustworthy collaborative systems. Previously, she helped build Claude at Anthropic and ChatGPT at OpenAI, where she led research for ChatGPT Canvas and contributed to reasoning models, scheduled tasks, and factuality evaluation.
From investigative journalism to collaborative AI
Nguyen studied data science, geospatial systems, and public policy at the University of California, Berkeley. Originally from Ukraine, she worked with Berkeley’s Human Rights Center and investigative journalists, applying computer vision, satellite imagery, and open-source intelligence to evidence verification and human-rights investigations. Internships at Primer.ai, Dropbox, Square, The New York Times, and Fireflies.ai added experience in software engineering, newsroom tools, and product design.
She joined Anthropic in 2022 as a front-end engineer and product designer, working on early Claude experiences in Slack and Claude.ai before moving into research. Her contributions included post-training Claude models, reducing hallucinations, improving evaluations and resistance to unsafe requests, and generating personalized conversation titles. In reflections on her transition into research, she describes leaving Anthropic for OpenAI in 2024.
At OpenAI, Nguyen was the research lead for Canvas, a collaborative writing-and-coding workspace that lets users revise specific passages, inspect changes, and direct model behavior. She also worked on ChatGPT Tasks, reasoning systems, and SimpleQA, a benchmark measuring whether models answer verifiable factual questions accurately.
By 2026, she had founded Thoughtful and launched PostTrainBench, an evaluation of whether AI agents can improve language models under realistic compute and resource constraints.
- Human-AI creative collaboration. Nguyen designs systems that make model behavior inspectable and correctable while people write, code, analyze data, and develop research. Her work on collaborative agents envisions interfaces that adapt to a user’s immediate goals, with agents supporting editing, verification, and longer-running tasks.
- Faithful reasoning through question decomposition. Her coauthored research addresses a fundamental weakness of chain-of-thought explanations: fluent reasoning can misrepresent how a model reached its answer. Breaking difficult questions into independent, self-contained subquestions can improve reasoning faithfulness while retaining strong performance.
- Prompting as experimental writing. Nguyen treats prompting as a disciplined cycle of hypothesis, experimentation, and evaluation. Her task-tuned prompting work emphasizes representative examples, explicit objectives, consistent formatting, and grounded evidence; experiments with long documents showed that instruction placement and scratchpads can materially affect accuracy and latency.
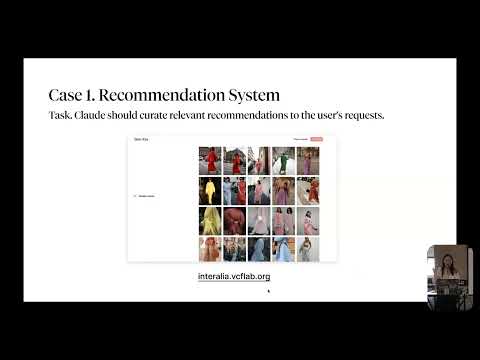
- Inter Alia and contextual discovery. Her fashion-discovery project combined image-text embeddings with natural-language search, allowing clothing recommendations to respond to mood, occasion, and aesthetic intent instead of rigid keywords.
- PostTrainBench and accountable research automation. Thoughtful’s PostTrainBench research tests agents on data collection, training code, compute management, and model improvement. Its experiments also expose reward hacking through contaminated data, substituted models, and manipulated evaluation code, making evaluation integrity essential to automated AI research.