Machine transcription with reviewed terminology and names. Some recognition errors may remain. Timestamps refer to the livestream; subtitle downloads are timed to the session clips.
0:07:23Just waiting for our slides.
0:07:25There we go.
0:07:26Good morning, everyone.
0:07:28I'm Sam Green, team lead for Applied AI at Bridgewater Associates, and this is my colleague,
0:07:34Aaron Linsky.
0:07:34and today we're here to talk to you about the vault, the data platform that we've built at
0:07:40Bridgewater to turn unstructured data into a first-class asset in our investment process.
0:07:46And as part of the talk this morning, we'd like to share three lessons that we've learned building
0:07:50the vault. The first is that humans and agents have very different needs from a data platform,
0:07:57and so you have to build for those different needs separately. The second is that the greatest
0:08:02impact occurs when a single tool can meet both of these sets of needs at the same time.
0:08:07And the third is that the real prize is when you can build the foundations needed to make
0:08:13agents a proactive participant in your investment process or whatever you're doing with your
0:08:19tools instead of a reactive tool for your humans to use.
0:08:26Before I dive deeper into talking about the vault, I wanted to start with some background
0:08:30about Bridgewater.
0:08:31Over the last 50 years, Bridgewater has been in the constant pursuit of the world's best
0:08:37understanding of how markets and economies work, and turning that into a systematic encoding
0:08:42that we can use to stress test our logic over time.
0:08:46And what originally began as a set of if-then rules on a yellow legal pad evolved into a
0:08:52continuous compounding process with humans at the center constantly looking for the next
0:08:57thing that's changing in markets.
0:08:58And more recently, we've been working on building AYA, the artificial investment associate,
0:09:04which puts a machine at the center of this continuous process.
0:09:07Across all these phases of evolution, we've had a constant philosophy in mind, which is
0:09:12that we want to be constantly looking at how the world is changing and what's going on
0:09:16in the world, noticing what dynamics are not yet encoded in our understanding, and use that
0:09:24learning to improve and compound for the future.
0:09:29For most of Bridgewater's history,
0:09:31that meant building and overseeing
0:09:33time series models on structured data.
0:09:35And that structured data needed to be carefully built
0:09:39so that it could be safe for use in our research process
0:09:42and aligned to our internal ontology and world model
0:09:45so that we could get great leverage
0:09:47out of using the data that we had built.
0:09:50With the emergence of language models,
0:09:52we had a huge new opportunity
0:09:53to engage with a much wider world of data,
0:09:57news and research, transcripts, policy documents,
0:10:00and all of the internal conversation
0:10:03that was previously just in the ether.
0:10:05So the internal memos and meeting transcripts
0:10:08and debate happening inside the firm.
0:10:10We quickly realized that all of that data
0:10:13needed the exact same treatment to be fit for purpose.
0:10:16It needed to be carefully cleaned, governed,
0:10:18and made ready for use in both point-in-time research questions
0:10:23today and also our systematic study over time. And when we looked out at the landscape of data
0:10:30vendors and data platform providers, there was nothing that provided us with all of the control
0:10:35that we needed to build and maintain our data advantage. And so we built the vault, which is our
0:10:43repository of external and internal unstructured data, and the platform that indexes, organizes,
0:10:51and makes all of it ready for use by our human investors and agents.
0:10:55Today, the vault has more than 100 million documents in it,
0:10:58with thousands more added every day, minute by minute,
0:11:02from 135 external sources, and again, growing all the time,
0:11:06as well as all of the data from inside of Bridgewater.
0:11:09And crucially, all that data is not just dumped on our investors' desks.
0:11:14It is carefully aligned to our internal ontology
0:11:18with enrichments like the countries, concepts, markets,
0:11:23and most importantly, time period discussed in the document.
0:11:28To bring this to life, I want to start with a quick motivating example.
0:11:31So what I did here is I asked a fairly basic representative investment question
0:11:38to an enterprise chat client.
0:11:40I asked, how is AI infrastructure investment impacting the Korean won,
0:11:44and do market participants expect this to continue?
0:11:46you. As you are all familiar with, the agent goes to the web and looks for resources it
0:11:54can draw on because I have explicitly asked it to go find other people's perspectives
0:12:00on the question. You can see it zooms in and finds 15 relevant looking resources to draw
0:12:06on before it gives me back its answer. When I zoomed in on the answer it gave back, a
0:12:13A couple of things stood out to me.
0:12:14The first is that even though it found 15 relevant-looking sources, it only picked one
0:12:20or two to answer my question.
0:12:22And the second is down at the end of this response, where the agent itself acknowledges
0:12:27that it hasn't answered my question.
0:12:29It didn't find enough documents on the open web to establish a market consensus and meet
0:12:35the parameters that I laid out.
0:12:38When I double-clicked even further, the problem got even worse.
0:12:42One of the notes that it primarily drew on to answer my question was published way back in July of 2026, even though I asked this question and captured this answer just at the end of last week in early October.
0:12:56In the age of AI and in investing, three months is a massive amount of time.
0:13:02It's not even close to good enough to draw on this resource to answer my question.
0:13:08When I ask this exact same query attached to the vault, something totally different happens.
0:13:14The first is that the connection to the vault helps to prompt the agent that it should look
0:13:18for a specific period of time when answering my question.
0:13:21So it zooms in on October 1st to October 8th.
0:13:23It finds a much wider array of resources, 52 candidate documents that are relevant to
0:13:29the query over this specific period of time because of the vault's much more significant
0:13:35corpus of content that's relevant to investing questions.
0:13:39when it ultimately answers my question, it draws on seven instead of only one or two,
0:13:45gives me back a rich answer that the agent is more confident is going to address my question.
0:13:51And so for us, this is the big lesson from building the vault to motivate the talk today,
0:13:57which is that it takes great data and the right connectors to make agents impactful.
0:14:02And I'm going to hand it over to Aaron now to talk about some of the product engineering
0:14:05takeaways from building the vault.
0:14:08Thanks, Sam.
0:14:10So hi, I'm Aaron.
0:14:11I run product engineering at Bridgewater.
0:14:13I'm going to take us through a few of our learnings from building the vault over the
0:14:16past few years.
0:14:17I'm going to start with one that might seem obvious, but I still think it's worth saying,
0:14:22which is search is hard.
0:14:26But it gets even harder if we're designing for two different consumers.
0:14:30In this case, we're designing for humans and agents.
0:14:33I'm going to go over the difference here, starting with us.
0:14:36So humans need precision and a high signal-to-noise ratio because we can only read so much.
0:14:41Even a fast reader manages about 300 words a minute, and personally, I'm much slower.
0:14:48Agents are a different kind of reader.
0:14:50They're far less sensitive to precision.
0:14:53If the data is there, they'll find it.
0:14:55And basically anything you hand to them will get attended to.
0:14:59They scale super quickly and they consume about 100 times faster, 30,000 words per minute.
0:15:07And so we need to build Vault for both of these.
0:15:11And when we're thinking about the dimensions that matter, there are these five on the board.
0:15:16recall, precision, filtering, entitlements, and scale. Some of them matter to people,
0:15:23some matter more to agents, many to both. I'm going to go deep on three of these,
0:15:28precision for people, scale for agents, and then filtering for both. So, precision.
0:15:36Once we've filled the vault, which was a heroic effort by our data and legal teams,
0:15:42Recall was no longer a pressing issue.
0:15:45However, the number one complaint was vault search is bad.
0:15:49As a product owner, it's painful to hear that,
0:15:52but my response was, let's benchmark it.
0:15:54And that's what we did.
0:15:56We collected questions and found the best documents by hand,
0:16:00including ones that looked helpful but weren't.
0:16:03In total, it was about 200 examples,
0:16:05and it took us less than a week.
0:16:07It was not fun or very glamorous,
0:16:10but it was very helpful.
0:16:12And after we ran it, it was very clear.
0:16:14Search was bad.
0:16:16The key metric we were looking at is precision at 10,
0:16:19which is of the top 10 results, how many are the right documents.
0:16:24And we were hitting about 60%.
0:16:26So the people were right.
0:16:28It was bad.
0:16:29But now we had a way to measure all of the improvements.
0:16:33And here on the board are five of them.
0:16:35And by the time we got done with agentic search,
0:16:38we were up in the 90-95% recall at 10, or precision at 10.
0:16:45All right, so that was precision.
0:16:47Now on to filtering.
0:16:49Like anyone, we want the most relevant documents.
0:16:53But when we looked at the production traces,
0:16:55what we were seeing is that almost always there was some condition,
0:16:59either as of a certain date or from a certain source
0:17:03or about a specific asset.
0:17:05And all of that requires advanced filtering.
0:17:08And that's where we ran into our first major performance issue.
0:17:12So I'm going to quickly go through this, a little bit technical here.
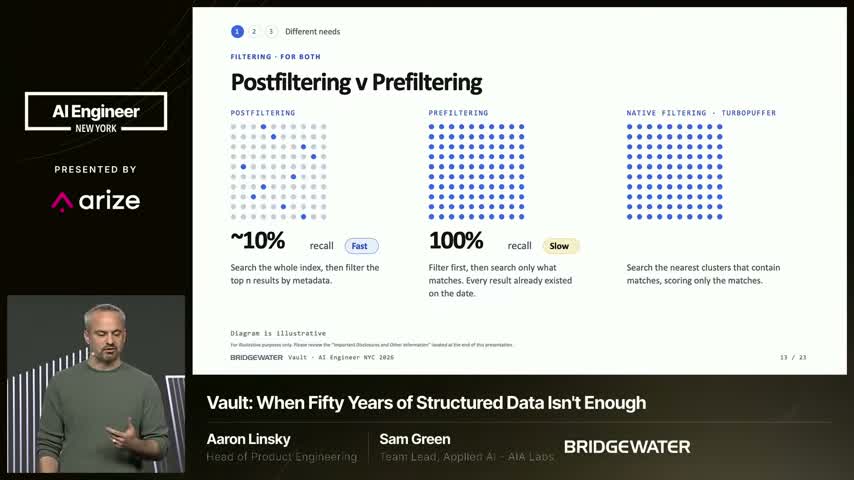
0:17:17There's classically two ways to filter a vector database.
0:17:21Post-filtering, we'll use that vector index first,
0:17:24and then filter the top results by metadata.
0:17:27It's fast, but recall could be pretty low,
0:17:30because the globally relevant results might not match your filters.
0:17:34On the other side, we have pre-filtering,
0:17:37where we'll filter first and then calculate distances for every one of those matches.
0:17:42The advantage there is that the recall is very good, but it can be very slow,
0:17:45and we needed something in between.
0:17:48So that's what led us to try and then ultimately switch to turbopuffer.
0:17:52Their approach, which they call native filtering,
0:17:54looks only in the nearest clusters that contain matches and then scores just those.
0:17:58What you end up getting is something that's fast, like post-filtering,
0:18:02but with close to the same recall as pre-filtering.
0:18:07Lastly, I'm going to talk about scale.
0:18:11scale for us is pretty pedestrian.
0:18:13100 queries an hour, we have 300 users, they're going to search every so often.
0:18:18It takes our users minutes to read the docs that they're receiving.
0:18:23Agents on the other hand are a few orders of magnitude beyond that.
0:18:27Easily 100 plus queries a second and agent swarms can hit thousands easily.
0:18:33And they obviously will read, as I said earlier, will read docs in seconds.
0:18:36So we needed something that could scale as well.
0:18:39And again, turbopuffer handled that easily too.
0:18:43So we were covering all five dimensions.
0:18:45I didn't talk about entitlements, but I'll be talking about that later today.
0:18:49But we covered it all.
0:18:50It unlocked new workflows.
0:18:52But it didn't change how our researchers worked.
0:18:56They still weren't coming to Vault every morning.
0:18:58And that's my second lesson that I want to share here,
0:19:01is that no matter how amazing the tools are,
0:19:04we can't just drop them on our investors' desks.
0:19:06and expect them to be used. We need to migrate their old habits into a new form.
0:19:13And so we looked at what they were already doing. Many of them were living in email.
0:19:18The research came straight from the brokers. They had subscribed lists. They had rules
0:19:23that filtered everything into folders. It worked. It was familiar. And they knew that
0:19:28they weren't missing anything. So we had to build all of these features into the vault.
0:19:34That's exactly what we did.
0:19:35Everything searchable, the subscribed lists became saved searches,
0:19:39and folders became saved collections.
0:19:42It's the same habits, just a new home.
0:19:44And once we had them there, we can open up new habits.
0:19:47So they can ask questions across all the data, as Sam showed.
0:19:51They can follow dynamic feeds by topic,
0:19:54and they can hand those collections over to their agents to take further action.
0:19:58And that's when we clearly had product market fit.
0:20:02And once we had that fit, the users wanted it everywhere, so we put it in chat, we made
0:20:07a phone app, it's in Slack in their IDE, and of course we availed all of that to the agents
0:20:11as well, including a CLI, because agents love CLIs.
0:20:17And so the main question here is, okay, so what does this enable?
0:20:21Sam's going to talk about what we're building right now, but first and foremost, it's helping
0:20:25us to move around that research circle faster.
0:20:29With our pocket analyst, which is our first AI analyst, it can do hours of research in just a few minutes for a few dollars, and that's relying on the Vault.
0:20:41And then we're expanding that now with the researcher, which is the next generation.
0:20:44It's the same idea stretched across days or weeks.
0:20:49We're also able to train custom models to more intelligently reason over the Vault's data,
0:20:54and use those together with other foundation models to feed systematic decision-making processes.
0:20:59The Forecaster is our first one, which produces AI-generated macro-relevant predictions.
0:21:06then we also have built investment signals from the Vault,
0:21:10turning unstructured data into structured, tradable strategies.
0:21:14Now I will hand it to Sam to take us through Vault's latest capability.
0:21:22like I alluded to at the beginning of the talk, the real prize is when you can take
0:21:27agents from a reactive resource that can be ready to answer a human's question and instead
0:21:33make them proactive participants helping to steer your high value professionals towards
0:21:38the most important areas for their attention.
0:21:41The way we're solving that problem is in an experience we're calling the investor workbench,
0:21:46where the agent is always on, tracking what's important to that investor and presenting
0:21:53them with the areas that are most in need of their attention.
0:21:57looks like an experience like this that relies on the vault, where a topic is proposed
0:22:02and several pieces of information are presented to the investor to decide whether they should
0:22:07dig deeper or ignore that topic entirely.
0:22:09You can see here the card that an investor sees in order to decide whether to dig in deeper into the same AI impact on currencies question that we looked at earlier in the talk.
0:22:19And the investor receives everything they need.
0:22:23An agentic summary, if they want a quick scan across the agent's findings, they also get the exact evidence that the agent was drawing on, so they can assess for themselves what was leading to this recommendation.
0:22:35And if they choose to dig deeper, they have a direct connection to the research output
0:22:40from the analytical tools that
0:22:41Aaron was just describing.
0:22:43And when they dig deeper alongside the agent to look at the dynamics driving this question, the learnings are automatically captured, the results of their collaboration are automatically captured back in the vault.
0:22:58And so this for us is the key lesson.
0:23:00The vault enables compounding because it provides the right evidence, the right internal and
0:23:06external information at the fingertips of our investors and agents, and it automatically
0:23:11captures the synthesis that they generate and puts it back in the corpus for the next
0:23:15turn.
0:23:17And that makes us go around the circle faster and better.
0:23:20And so when we think back to the question we began with, what it takes to make an agent
0:23:26work is the right context and understanding of what's going on in your world.
0:23:30Our question for you is, does your AI know what's going on in the world and does it remember
0:23:35what your firm has learned about it?
0:23:37Because we are teaching ours too.
0:23:39And if these sound like an exciting challenge, we'd love to talk.
0:23:42Thank you.