Machine transcription with reviewed terminology and names. Some recognition errors may remain. Timestamps refer to the livestream; subtitle downloads are timed to the session clips.
0:24:23Hey,
0:24:25All right, I precariously balanced my water over there.
0:24:28My name's John Feminella.
0:24:29I work on AI architecture and engineering at Two Sigma,
0:24:33which is a hedge fund here in New York.
0:24:35Before I get too far into things,
0:24:37I have a legal disclaimer slide that I have to show you
0:24:40that says two things.
0:24:41One, I promise not to sell or market or offer you any securities
0:24:45at any point in this talk.
0:24:46and two, everything in this is my own opinion
0:24:49and not the opinion of Two Sigma.
0:24:51Thanks for indulging me.
0:24:52If I don't say those magic words,
0:24:54the 5G microchips implanted in me will explode.
0:24:59So that slide is a good example, actually,
0:25:01of how our industry is regulated.
0:25:03And as a regulated company with lots of controls,
0:25:06I think one thing that's always interesting
0:25:08is to explore what happens when controls fail
0:25:11because that gives you a good idea
0:25:13about why the controls were there in the first place.
0:25:15And so I'd like to tell you a story about that by showing you another legal slide.
0:25:20After August 2020, a very interesting contract clause suddenly started showing up in a bunch
0:25:25of commercial loan agreements.
0:25:27And this clause essentially tries to prevent a certain scenario from happening.
0:25:31And it's complicated, but I'll explain it like this.
0:25:33Let's say that you're a lemonade stand business, and you borrow money from a lender to capitalize
0:25:38your lemonade stand.
0:25:39and the bank that's overseeing that transaction,
0:25:42that's in the middle between the borrower and the lender,
0:25:47sends the lender all of the money that you owe in a catastrophic mistake.
0:25:53You'd probably be mad and want the money back,
0:25:55but the lender might also say,
0:25:56no thanks, you paid us back and we're all good,
0:25:58so we'd rather keep the money.
0:26:00Something like this happened in August 2020.
0:26:03Revlon, the cosmetics company, had borrowed money under a big 2016 term loan.
0:26:09And that loan was split up into a bunch of pieces across 300-plus lenders, hedge funds, credit funds, CLOs, other banks.
0:26:17And in the middle is Citibank, the administrative agent.
0:26:20Being the agent in this kind of transaction means that you're performing the plumbing that connects the borrowers with the lenders and managing the lifecycle of the loan.
0:26:28So in this transaction, Revlon pays Citi, and then Citi pays the lenders.
0:26:32And Citi's not lending its own money.
0:26:34It's just in the middle, moving people's money around.
0:26:37So here's the plan for August 11th, 2020.
0:26:41Revlon would pay about $8 million of accrued interest to both groups,
0:26:45and the lender's principal would roll into this new facility.
0:26:48That's an exchange of paper, not cash.
0:26:50So the remaining lender's principal would stay put,
0:26:53and the idea here is that only interest should be going out.
0:26:56Principals should not be moving at all.
0:26:59And the bank had a piece of internal processing software called FlexCube.
0:27:04Isn't that a fun enterprise software name?
0:27:06in FlexCube, the easiest way to do this kind of transaction
0:27:10is to pretend to record it like Revlon were paying off the entire loan.
0:27:15And that triggers the correct interest payment calculations to everyone.
0:27:19You can probably guess what's about to happen next.
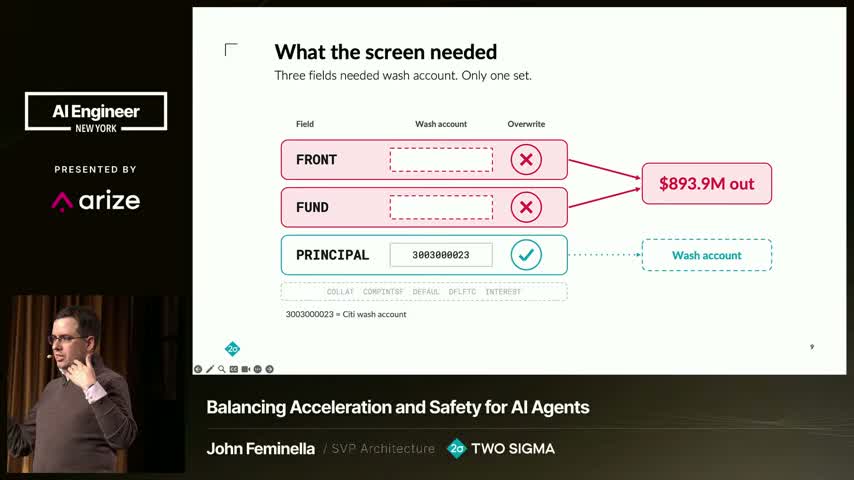
0:27:21So you're supposed to send the principal portion
0:27:24to an internal WASH account that you own as the bank
0:27:27so that it's booked and recorded correctly,
0:27:30but it never leaves the bank's perimeter.
0:27:32So keep your eye on that WASH account.
0:27:34What was supposed to happen is that the boxes labeled front and fund and principal should
0:27:40all include the WASH account number and should all have a check box checked next to them.
0:27:44So unfortunately it turned out that was what needed to happen, but for various arcane reasons
0:27:50the boxes were not checked.
0:27:52And although FlexCube pops up a warning notification that says, uh-oh, money is about to leave the
0:27:57bank, are you sure you want to do this?
0:27:59That was correct.
0:28:00Money was supposed to leave the bank because they were making the interest payments.
0:28:03So the three approvers who were supposed to approve that looked at it and said, yep, that's
0:28:07the right thing that's supposed to happen.
0:28:09And although that warning notification popped up, the human operators carrying out the transaction
0:28:14overwrote that.
0:28:15Remember, Revlon was making that interest payment.
0:28:17So the principal never went to the wash account.
0:28:20And instead, Flexcube sent the entire outstanding principal of the loan to all of the 300 lenders,
0:28:26about $900 million instead of $8 million.
0:28:29So every lender got the amount that they would have been owed
0:28:33if Revlon had paid the loan in full,
0:28:35but Revlon didn't want to pay off the loan.
0:28:36It wanted to hold on to its money.
0:28:38That was a great deal for the lenders,
0:28:39because remember, Revlon was in trouble at the time,
0:28:41so its loans weren't trading at face value,
0:28:43and getting all your money back on a deal
0:28:45that you thought was only worth 60 cents on the dollar
0:28:48is a great deal for you.
0:28:50So they didn't want to give the money back,
0:28:52even after Citi called them and said,
0:28:54please, that was a mistake, give us the money back,
0:28:55and their argument was,
0:28:56we shouldn't have to give the money back
0:28:57because you paid us in full, and that's how loans work.
0:29:00You eventually pay them back,
0:29:01and just because you paid it back at a different time
0:29:04than you were supposed to doesn't mean
0:29:05that we should have to give it back now.
0:29:07And so to prevent that from happening,
0:29:09commercial loan agreements everywhere started
0:29:11including a clause like that one.
0:29:13So what does a payment error at a bank
0:29:15have to do with AI agents?
0:29:17Well, the bank had this procedure, it had these controls,
0:29:19and everybody did what they thought the right thing to do was.
0:29:23That's the problem I want to talk about for the rest of this talk.
0:29:25Every day we're giving real agents real autonomy over systems like FlexCube.
0:29:30And how do we prevent accidents like that one from either from happening without locking everything down or just hoping we'll get lucky that they won't happen?
0:29:38So here's the crux of the issue.
0:29:40You can't really know in advance what an agent will do, right?
0:29:42There are these non-deterministic systems.
0:29:44And that sounds scary until you remember that humans are also non-deterministic systems and they're going to make mistakes too.
0:29:50And so most firms don't choose to say, well, in order to reduce the risk of humans making a mistake,
0:29:56we're going to lock them in rooms and prevent them from talking to each other,
0:29:58and they're all going to double-check everybody else's work.
0:30:00We allow them a certain amount of autonomy along with a certain amount of controls.
0:30:05So we give them boundaries, visibility, and we equip them with systems and controls
0:30:09that let them do their jobs effectively.
0:30:11So in this sort of model, safety and innovation are not opposite ends of a spectrum
0:30:16that you must trade off on.
0:30:17They're things that you can have at the same time.
0:30:19So I think you can have your cake and eat it too.
0:30:22And when we were thinking about what controls we wanted to apply to agents,
0:30:25we also looked at some approaches that didn't work for us.
0:30:28We don't want to sandbox or lock down everything,
0:30:30because a sandbox with no real access to systems is safe,
0:30:33but it's not very interesting or useful.
0:30:35If you let agents go wild and do whatever they want,
0:30:38that's maybe powerful and freeing from a cognitive perspective,
0:30:42but the isolation is very weak there,
0:30:45and that approach is generally not suitable for highly regulated enterprises.
0:30:48And then if you just have policy documents that agents look at or that are part of your
0:30:55specification for the prompt, that's also not very enforceable at runtime.
0:30:58You can't guarantee that that will be part of the enforcement controls.
0:31:02So what did work for us was thinking about what mix of controls would get us both safety
0:31:07and innovation at the same time.
0:31:09So how do we provide boundaries and stop problems but don't hinder folks from operating correctly?
0:31:15So we have a number of these controls, but today I'll talk about five of them.
0:31:18When I say controls here, what I mean are the guardrails and shared capabilities that let teams move in ways that don't hinder what they're trying to do.
0:31:28And we don't want to reach some chasm that we need to cross to let people get their work done and then make everyone wait while we build a bridge to get there.
0:31:39So these controls are composable.
0:31:41Each one does one job.
0:31:42And then together, they let us run agents with real autonomy at an appropriate level of safety.
0:31:49So the first problem is that agents were showing up everywhere.
0:31:53We have big teams with lots of agents running.
0:31:56We have small teams with a few.
0:31:57We have individual people running stuff in an uncontrolled way.
0:32:00And these come in every shape.
0:32:02Could be random chatbots.
0:32:03It could be MCP servers glued together in this Frankenstein hot
0:32:07podge.
0:32:08It could be cool notebook experiments.
0:32:09It could be really useful web tools for folks.
0:32:12But it's hard to answer when you look at that a few simple
0:32:16questions, like who owns this?
0:32:18what tools does it have access to, what should it be doing, what should it not be doing.
0:32:22And if you can't answer those kinds of questions, if you can't govern them,
0:32:25then you can't really also reuse that.
0:32:27So you're tempted to build multiple solutions to the same problem
0:32:31if you don't know about what exists already.
0:32:34And then the firm can't also govern those in any kind of legible way.
0:32:38So one thing the firms sometimes do here is add some kind of gate.
0:32:42Like don't let anything run until everything is registered and approved
0:32:45and has gone through this very onerous process.
0:32:48And that sounds safe, but if you look at what it does to the work,
0:32:51every idea, even some simple no-pick experiment,
0:32:54is going to wait in line behind something that's really risky.
0:32:57And we don't want to subject everybody who's given the diversity of agents
0:33:03to exactly the same process.
0:33:04So most people are going to give up,
0:33:06or they'll just get pushed to some shadow IT,
0:33:08less governed path that is less visible,
0:33:12and then we don't get to see anything at all.
0:33:14So that's what motivated the first control is an agent registry.
0:33:16You can't govern it, you can't see, so the agent registry makes agents legible, and it
0:33:21registers, retrieves, and discovers the key
0:33:23facts about agents that we want to know for any agent.
0:33:27So those are things like which tools it declares, what endpoints it's going to talk to, which product does it belong to, who owns it.
0:33:34And humans, other programs, other agents can then use the agent registry to decide what's available at the firm, whether that's useful for them, and to go use that as a source of truth for other questions.
0:33:46So this doesn't require extra effort on your part.
0:33:49It just happens when you use one of the firm's approved agent building frameworks.
0:33:53It's automatically registered.
0:33:54All that information is recorded there for you.
0:33:56And if you want to do a manual registration, you can certainly do that.
0:34:01So the second problem we have is that now that we've got all these agents doing all
0:34:05these things, we quickly notice that what they're doing is really different.
0:34:09And that means our agents carry really different risks, right?
0:34:13So a thing that summarizes Jira or linear tickets is really different than a production
0:34:18deployment agent that can touch a running system.
0:34:21And if we try to use the same review process to cover all of these agents, then every agent
0:34:27is waiting in the same queue for weeks for human review.
0:34:29And if people are going to route around slow processes, then we wind up in the same situation
0:34:34that we had before.
0:34:36So again, you might be tempted to say the answer is something like really detailed,
0:34:40heavy manual review by all of these different constituencies. Again, that feels safe, but now
0:34:45we've got a trivial summarizer waiting two months for the same sign-offs as an agent that is touching
0:34:51production systems. And most of the good agent ideas, most of the ones that have value right away,
0:34:57start out as small experiments, and you don't want those people to wait in the same line as the stuff
0:35:02that's touching production right away. So the reviewers are drowning in these low-risk requests,
0:35:07and the high-risk ones have to share that attention pool.
0:35:10So we don't want to trade away that speed if we can help it.
0:35:13So again, because not every agent needs the same review,
0:35:16and because most agents are purpose-built rather than open-ended,
0:35:19and when I say open-ended here,
0:35:20you can imagine coding agents like Pi or Claude Code.
0:35:24When you open them and you start typing,
0:35:26Claude Code or Pi doesn't know what you're about to ask.
0:35:30It doesn't circumscribe its purpose in any particular way.
0:35:33But most of the agents that are deployed in enterprises
0:35:36do have very specific purposes. When you're engaging with that agent, it's to do something
0:35:40specific that's well known and well understood. So they have a very specific reason for existing
0:35:45and a very circumscribed purpose. And you can tell these agents apart from each other by looking at
0:35:50what they declare up front, their tools, the endpoints they access, the controls that are
0:35:55applied to them, etc. So the third problem is that if you know about your agents and what they're
0:36:03doing, you'll quickly notice that many agents don't talk to each other.
0:36:07Sorry, they don't talk to just one thing or in just one capacity.
0:36:10The more open-ended the agent is, the more it looks like a Claude Code or Pi, the more
0:36:15it can do a variety and a diversity of different things.
0:36:18Call an internal API, run a tool like a web search, that sort of thing.
0:36:23And each one of those is a different opening, a different door to a different kind of risk.
0:36:27And if you give an agent an entitlement for a role account, then it can do a lot more
0:36:32damaged than something that's just going to read a public web page, for example.
0:36:36So the question is not, can this agent do X, but what's the granularity that we need
0:36:41to solve for for the agent to act successfully?
0:36:45And again, one tempting answer is to kind of be heavy-handed here, or to give every
0:36:49agent the same short allow list of stuff that's safe to do, and then block everything else.
0:36:55That's safe, but it's also useless.
0:36:56An agent that can't search, or can't call an API, or can't do any of those things without
0:37:02asking somebody first can't really do the work that it was intended for. And then
0:37:06teams either give up on those agents or they find a way around the wall and
0:37:10both outcomes are costly. So a wide kind of blanket block on everything trades
0:37:15away the innovation that we want to preserve and avoids making a real
0:37:19decision about risk. And as author John Shedd wrote, a ship and harbor is safe,
0:37:24but that is not what ships are for. So the fix here is to let agents declare
0:37:29their purpose upfront and say what tools they're going to use or what tools they
0:37:35need access to. So in the second column here we might say that a research
0:37:41summarizer is going to be allowed to use a web tool to access research, but for a
0:37:48release deployer agent we're not going to allow them to do that because they
0:37:51have no reason to use that tool. And so if they try to ask for it they won't get
0:37:55it by default. So we don't need to make this kind of decision for every tool.
0:37:59the agents just have to say which tools they want.
0:38:02And you're, as the agent author, you're in the best position to say,
0:38:05I need these four things out of the 500 that are available.
0:38:10So the way we need to enforce that is that when agents run in our managed environments,
0:38:15they look at the registry that we talked about before
0:38:19to look up what policies apply to it at initialization time.
0:38:23And that policy gets translated into enforceable statements,
0:38:26like which endpoints are you allowed to access, which hosts are you allowed to access,
0:38:31what other types of resources are available or not available to you.
0:38:34And in this way, nobody's writing a ticket every time they need to change the access.
0:38:39Nobody's going to talk to IT or some other group outside of your team.
0:38:44As long as you conform to the risk score that we talked about before
0:38:47and you're in the agent registry, you're governed, you're approved.
0:38:51So this is how we keep the cost to teams really low for deploying, building, running agents.
0:38:57And the same control architecture works in a variety of settings.
0:39:01The next thing we noticed was that teams were building a ton of different ways to evaluate agents,
0:39:06and every stack looks different, and some teams don't build anything at all.
0:39:09Sometimes you build this really detailed stack for how your models work.
0:39:13Sometimes there's nothing.
0:39:16And I think in general we'd be upset if teams were not writing unit tests, right?
0:39:21And we consider evals to be kind of the same thing.
0:39:24If models are changing, that's like a runtime dependency that your application has.
0:39:28And if your agent is going to change models, it doesn't know without the evals what's going to happen to its outputs and to the quality of those outputs.
0:39:38So, again, one tempting answer here is let's have some kind of central evaluation methodology
0:39:43that waits for a full eval suite and a committee sign-off.
0:39:47But now every prompt tweak, every one-line change is going to sit in that same queue.
0:39:53So we don't want to put more decisions on more reviewers for things like that.
0:39:57We don't want to trade away that iteration.
0:39:59So again, you wouldn't ship software without unit tests, so agents need evaluations for
0:40:04the same reason, and we want to provide the stuff at the level of the firm that's going
0:40:09to be the same for everybody.
0:40:11So Team A writing evals, Team B writing evals.
0:40:14They're both going to have many of the same features.
0:40:16So we want to have one shared approach to how we do evals, and have the shared approach
0:40:21be something that's run by the firm and available to everybody for doing their evals.
0:40:25So that covers all the common parts of evals, and all you've got to do is just write what's
0:40:29true about your agent.
0:40:33And finally, maybe you've had the experience of being asked to approve lots and lots of
0:40:37individual agent actions when there's a human in the loop.
0:40:40So that's fine on a small scale, but once you're operating agents in parallel or in
0:40:44production, this becomes completely onerous and review requests come in faster than anybody
0:40:50can be expected to approve them.
0:40:52After the first few times this is happening, you succumb to review fatigue where you just
0:40:56see yes, yes, yes, yes, yes.
0:40:57and eventually you click yes on something that's activating a nuclear bomb.
0:41:02So you don't want to click yes by reflex, but that's going to happen inevitably.
0:41:07One recent example of this is earlier this year, a director at an AI research lab
0:41:11told her open claw agent to suggest emails to delete from her inbox and wait for her approval.
0:41:16But her inbox was so large that eventually the agent compacted its context
0:41:20and lost the part that said, wait for my approval.
0:41:23And then it deleted hundreds of emails and didn't stop when she told it to stop on her phone.
0:41:27So again, you might be tempted here to make a human approve every action, but that's not
0:41:31the right way to do it.
0:41:32A better approach is to let these independent, conservative classifiers make decisions about
0:41:39routine calls, and then send a person only the requests that are most important, the
0:41:44ones that are most likely to make a difference.
0:41:46If you're saying yes, 99.99999% of the time, then that's probably just a rule that the
0:41:51agent should follow, not a request you need to ask the human for permission for.
0:41:55and the stuff that's unclear or ambiguous or potentially dangerous, yes, surface that to a human,
0:42:00or if it's definitely just dangerous, deny it outright. So this is a way to not have to do all
0:42:07the review work all the time. So we want to take the same approach for both explicit,
0:42:12when explicit rules apply, we want deterministic fast paths. When explicit rules don't apply and
0:42:18there's some ambiguity, we want a classifier to do that work instead. So putting those five pieces
0:42:23back together. You create a registry so that every agent is visible from the day it's created.
0:42:27You score each agent so human review goes in the right spot. You run agents on guardrails so that
0:42:33they only touch what they need. You share evals and metrics so everybody is reaching the same bar
0:42:38without having to reinvent the wheel. And then finally you govern your runtime to make sure that
0:42:42classification happens there and not somewhere else. So each of these controls works together.
0:42:48So I'll leave you with one question.
0:42:50Why do cars have brakes?
0:42:52It's not just so that you can stop, it's so that you can go fast and stop safely.
0:42:57So controls for our agents work the same way.
0:42:59Thank you very much.
0:43:00I'm John Feminella, and I hope you had a good time.