Machine transcription with reviewed terminology and names. Some recognition errors may remain. Timestamps refer to the livestream; subtitle downloads are timed to the session clips.
6:47:47Hello
6:47:47Exciting to be here. My name is Frank. I work at Coatue which is a technology investment firm across public and private markets
6:47:54So, in our business, what you really need to do is be able to take high conviction bets
6:48:00on big themes and watch those play out.
6:48:03I think, honestly, a career is the same way.
6:48:06And last year when I joined Coatue, the bet that I wanted to make was I think that agents
6:48:11will have an even bigger impact in investing than they did at coding.
6:48:15I know that's a big statement.
6:48:16We're all here because of the transformative impact that AI has had in coding.
6:48:21But I really believe it strongly.
6:48:23And today I want to talk a little bit about the framework that we use to actually realize
6:48:27that impact.
6:48:29So, at a high level, you can think about a hedge fund as a function that takes in two
6:48:34parameters, context external and context internal, and spits out one tuple.
6:48:40Selection, size, timing.
6:48:44stock, how much, when.
6:48:47And I think this is a good framework to actually ground our work, which is we are trying to
6:48:54solve this compression problem of how do you take all the information in the world and
6:48:58spit out this one simple tuple and the product that we provide is essentially a time series
6:49:05of this tuple that constructs a portfolio.
6:49:08let's start from the top, which is the inputs.
6:49:11simple philosophy.
6:49:13We use our screens, we look at stuff, we do work.
6:49:17Every single thing that a human can see in pixels on the screen, an agent in your building
6:49:21should be able to see via API.
6:49:23The analogy I use is imagine you brought the smartest people ever, the greatest investors
6:49:29alive and you brought them into your company but you gave them a computer without logins
6:49:34to 75% of your services.
6:49:36It's almost immaterial how smart this system is if it doesn't have the tools to actually
6:49:41action that.
6:49:42So the two parts, external context, no surprises here, think the news, prices, filings, all
6:49:51of that should be easily accessible and not via dragging and dropping, copy and pasting,
6:49:56like directly via API.
6:49:59Internal context is just as important, right?
6:50:03So this is your own firm situation.
6:50:06So that might be our current positions, potential liquidity and risk requirements we have around
6:50:10certain names, and past case studies or history with a certain sector or stock or management
6:50:19team.
6:50:20That is all super important.
6:50:21So this is the foundation, and I think, no credit to me, Coatue has been an amazing leader
6:50:26on this for over a decade.
6:50:29It is both technological and cultural.
6:50:31We have an amazing data science team, amazing processes, amazing systems that bring all
6:50:36this in, and just as importantly, we have a culture that is super, super rigorous and
6:50:42built from the ground up to capture all this insight.
6:50:45For decades, we filed every single note about every single trade, about every single decision
6:50:50we made or didn't make about what went well and what didn't go well, and that has poised
6:50:54us to expose us to AI.
6:50:57If you think about it, I probably can't just take all of those things, jam them into a
6:51:03context window and get my magic three numbers and go home.
6:51:07It can't be that easy.
6:51:09You probably have to break down this function a bit further.
6:51:14So maybe the first step is I take in that external and internal context and I gather
6:51:20it.
6:51:21I want to gather it, I want to filter out what is relevant and not relevant.
6:51:25Okay, well, I pulled some news articles about the MBA that probably isn't material to stocks,
6:51:30but this is related to local permitting that might impact data centers.
6:51:36There is a lot of nuance in this gather step.
6:51:41you will see probably the next step is I need to analyze that information and form
6:51:44a view.
6:51:46I need to think about what that means for the markets, public and private, and then
6:51:54I need to take that view and turn it into a decision.
6:51:57A decision object has these three parameters, these three sub pieces.
6:52:03You can see every single step has an input and an output, and the input for the subsequent
6:52:10step is the output that the previous function generated.
6:52:14I think as an engineer, this is a way for me to conceptualize the problem in a way that
6:52:20makes a lot of sense.
6:52:21But even this, it really can't be as simple as writing three functions.
6:52:26So let's just, to really appreciate the scope and understand the full complexity of the
6:52:33problem, let's look into the first step, a tiny sub piece of a tiny sub piece of just
6:52:38gathering information and let's do a case study on interpreting the news.
6:52:45So it's probably no secret to you guys that news from Asia and Korean media outlets has
6:52:52been super important this year because semis, AI, have been a huge, huge theme in the market.
6:52:59Huge theme.
6:53:00And I think this is an area where AI is poised to have a lot of impact.
6:53:05Reading Korean language news better than our completely non-Korean speaking staff.
6:53:12I think I have a good thesis that this might be a good use case.
6:53:15So you can imagine the first step is I have articles.
6:53:20I need to collect the articles.
6:53:23This
6:53:23could be an MCP, this could be a CLI, license the data feeds, clean the data feeds. There are a lot of ways to do this and a lot of dimensions of freedom for how you can even just write this simple piece. How do I chunk it when I pass it to the LLM? Do I want to pull the images as images? Do I want to pull the images and then turn the images into text? There are actually a lot of knobs here.
6:53:48I almost think about those knobs as hyperparameters in a traditional machine learning system.
6:53:53I think about each of these knobs as something for me to tune and optimize against.
6:54:00Obviously, filtration, we talked about it.
6:54:04There are probably Korean NBA fans, right?
6:54:06There is probably a bunch of stuff that is not necessarily material to the names and
6:54:14themes and stocks in our portfolio that really, really matter.
6:54:16So I want to make sure that I filter those out.
6:54:22There is this translate slash extract slash should I summarize, should I extract this
6:54:27into some sort of structured form.
6:54:29Again, so, so many ways to do this, so many ways to experiment, how to expose information
6:54:34to the model, and one of the reasons this is hard is it keeps changing.
6:54:39And obviously checking.
6:54:40Checking our own internal notes, our own internal views, potential conversations we have had,
6:54:46meeting recordings against these things.
6:54:48We actually need to cross-reference those things.
6:54:51Actually the idea of pulling information from disparate sources and cross-referencing them,
6:54:56that's super powerful.
6:54:58So you will see on the right here I have code, LLM, LLM, code, person.
6:55:03There's many, many ways to run these functions.
6:55:06I think about, oh, yeah, and finally, update.
6:55:10We update our views.
6:55:13There are many ways to run these functions.
6:55:15I think of each line as having a runner, and the most obvious one is code.
6:55:22Code is very good.
6:55:23It is fast, it is cheap, it is reliable, so for something like if the prices to earnings
6:55:30ratio is less than 15, I should just use deterministic code for that.
6:55:35Runner number two is statistics, classical machine learning, and you can imagine fitting
6:55:42the line to a regression for a specific pattern, this is very powerful because you can model
6:55:47much more complex relationships than just pure deterministic code.
6:55:52And for even more complex relationships, the reason we are all here, LLMs, AI agents, that's
6:55:58another type of runner.
6:55:59So for something like summarization, that's the state of the art.
6:56:04It's probably totally impossible to build a bunch of if statements that can summarize
6:56:10better than a modern LLM.
6:56:12Of course, people.
6:56:15People are important runners in the system.
6:56:18Imagine a function meeting the management team of a company.
6:56:22I probably don't want to send an LLM or an AI agent in to do that.
6:56:28I probably don't want to send an if statement into that meeting.
6:56:31I think there are many cases where because of judgment and the ability to navigate the
6:56:35real world and all of these things, a person is the best runner for a given piece of the
6:56:40function.
6:56:42I think this is a super, super important point.
6:56:45There is no glory in automating things for the sake of automating things.
6:56:49The goal is not to take as many things and make them LLM as possible for us.
6:56:54The goal is for any given piece of this function, what can I do to maximize absolute quality?
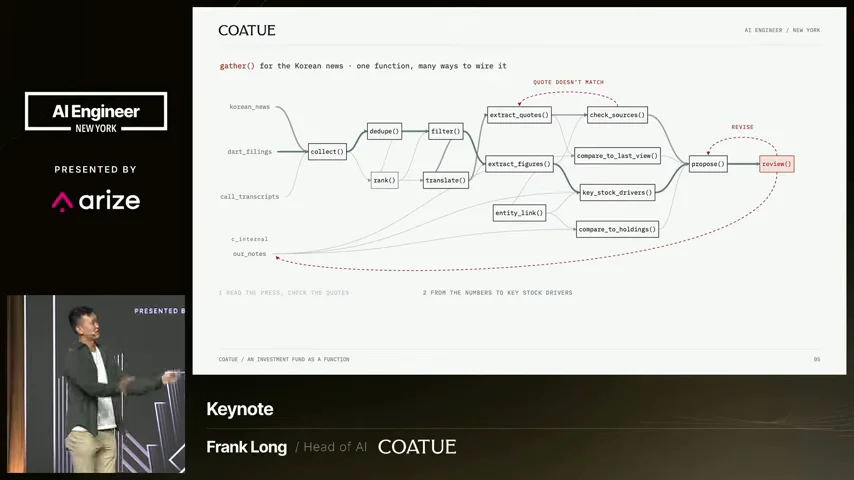
6:57:03And if you actually think about the function, it probably looks something like this.
6:57:07It's probably not just a linear statement of a bunch of different things.
6:57:11There's probably all kinds of branching logic and all kinds of ways to actually fork this.
6:57:16So maybe I want to collect the information and then translate it, and my main goal is
6:57:20to extract quotes and check those against sources to make sure that these are actually
6:57:24the things that people said, and that's my approach.
6:57:27But that might be totally wrong.
6:57:28Maybe what I want to do is I want to de-dupe and then I want to filter and then I want
6:57:33to pull external figures or maybe I want to do something totally different.
6:57:36I actually want to, I'm passing in a note first and I want to find other confirmatory
6:57:41data points or maybe I'm trying to red team.
6:57:43There's a million different ways to configure this.
6:57:46So yet again, more hyperparameters within the control flow, right?
6:57:52So many ways to think about just this very simple problem of pulling, filtering, summarizing
6:57:58aggregating the news for LLMs.
6:58:02And each of these boxes probably has an optimal runner, right?
6:58:09So the optimal runner might be deterministic code for collection, right?
6:58:15I'm pulling last 24 hours for a given source.
6:58:19That's deterministic code.
6:58:21Filtration?
6:58:23models maybe.
6:58:25LLMs?
6:58:25statistical methods, a combination, right?
6:58:29So this probably understates the complexity.
6:58:32The reality is most things are multi-runner.
6:58:34Most things have deterministic code plus LLM plus statistical method or human with LLM
6:58:39in conjunction.
6:58:41reality is it's probably combinatorics between my four buckets and there's even more
6:58:46buckets than that.
6:58:48Because within the LLM category I can tune the model.
6:58:52I can choose big model, small model, medium model.
6:58:55I can tune thinking effort. X high, high, medium, I can tune harness. I can choose the harness. I can
6:59:02choose which skills load with the harness. I can choose which hooks load with the skills.
6:59:05So yet again, more hyperparameters within my search space. I have an absolutely enormous
6:59:10amount of hyperparameters within my search space. And this is just for this one tiny problem, right,
6:59:15of just filtering the news. So the way to think about breaking down these problems is what can I
6:59:22actually compartmentalize in a way that we can understand and evaluate.
6:59:26That's what I'm hill climbing against.
6:59:28Otherwise I'm just tuning these things.
6:59:30I'm okay, that should actually be a machine learning system instead of an LLM.
6:59:34That should be a little model that we train.
6:59:36Oh, no, that shouldn't be a model at all.
6:59:38That should be an if statement.
6:59:39Or, oh, man, LLMs are really, really bad at translating that to portfolio impact.
6:59:44It should really be a human on that step, but they're using a deterministic system to
6:59:48help them search and pull the information.
6:59:51It could be all different things.
6:59:52And if you don't have a north star to hill climb against, you're just kind of, you're
6:59:57just fidgeting around.
6:59:59And I think I cannot convey enough that this is just one tiny thing we do.
7:00:04Imagine every single data source that we pull in, there's probably more than just three
7:00:09transformations to get them to the intermediate output.
7:00:11So the actual graph of Coatue and funds like Coatue, it actually probably looks, oh, not
7:00:18like this.
7:00:20is my screen saver.
7:00:22The actual graph probably looks something like this.
7:00:25It is probably massively complex.
7:00:28In each of those nodes, we just talked about at least ten hyperparameters with at least
7:00:3420 different values for them.
7:00:36So the search space is basically infinite.
7:00:39And figuring out how to actually lay this out in a way that you can comprehend both from
7:00:45technical perspective, but also absorb culturally, organizationally.
7:00:49That is the great challenge of applying AI in investing.
7:00:54And beyond investing, what we're really talking about is creating a state machine that can
7:01:00take information from the world and understand it well enough to make coherent decisions.
7:01:05There's use cases for this far and above, wider than just investment firms, in policy,
7:01:12in non-profits, in drug discovery, in corporate strategy.
7:01:16I think one of the most exciting things for me
7:01:19about being in forums like this
7:01:20is talking to other people in different spaces
7:01:23with different problems that kind of congeal
7:01:25on the same problem space.
7:01:27I'd love to keep talking about this.
7:01:29I'll hang out in the hallway afterwards.
7:01:30Here are my socials.
7:01:31And thank you, everyone, for your time.
7:01:34Thank you.