Machine transcription with reviewed terminology and names. Some recognition errors may remain. Timestamps refer to the livestream; subtitle downloads are timed to the session clips.
7:02:19Hello.
7:02:22I want you to zoom out for a second and think about if somebody were to tell you today that
7:02:29we would take all the information on the internet and then we would train a model on it and
7:02:35we would use that in order to solve scientific problems that were not on the internet.
7:02:39I think a lot of people would tell you that that's crazy.
7:02:44And what we're doing has a lot of parallels to that story.
7:02:48So if you think about how intelligence works, imagine for a second that you're in the movie
7:02:55Frozen and you're Olaf, the snowman.
7:03:00If Olaf was an LLM, and there's a scene which is one of my favorites, which is where he rolls
7:03:05down a mountain and there's a little stone that pops up and Olaf spreads out, temporarily
7:03:12becomes a disassembled snowman and then becomes an assembled snowman.
7:03:16Olaf knows how to do that because Olaf can observe as he is acting.
7:03:22Olaf can, unlike
7:03:23LLMs, which autoregressively predict tokens, constantly part of that behavior is that it's constantly observing as it is acting.
7:03:33And so this is the big difference between, you know, when you see LLMs try to solve robotics problems or when you look at native architectures like we're working on, it's very, very easy to think of LLMs in the demos to see on Twitter as the thing that will
7:03:48Solve everything, there are fundamental limitations where purpose-built models are a much better
7:03:54fit.
7:03:55Today I'm going to talk a little bit about what the other side of that coin looks like.
7:04:02For us, it all started with Medal.
7:04:04We built the largest video game recorder in the world, and we think of that as the internet.
7:04:11People use Medal to record themselves playing tens of thousands of different video games,
7:04:15And if you think about it, as a human, we can teleoperate a robot with the exact same
7:04:24brain that we played at video game, and in fact, in many cases, we also can use the same
7:04:33controller.
7:04:34So what this means is that the action space of video games, often because of game controllers,
7:04:38and the action space of teleoperations or the real world, in many cases is the same.
7:04:43And so every single robot, below certain degrees of freedom, ships with the game controller.
7:04:49The majority of the supply chains already work this way.
7:04:51And so we thought, what if you just take all of the action data that we get through the
7:04:56video recorder, which associates the inputs and the actions with the actual frames, we
7:05:02label the actions so we understand semantic meaning behind every action, and we use it
7:05:07to give it to a vision-based model.
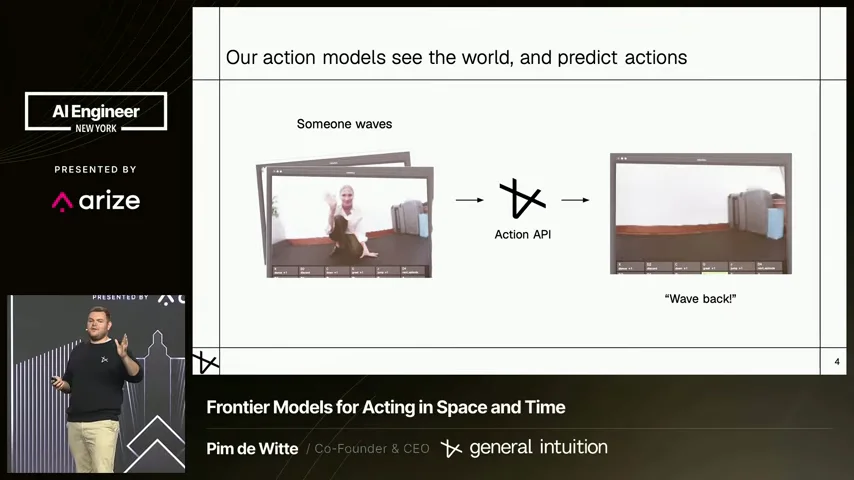
7:05:10What you see here on the left is just an intuitive way of how the model works.
7:05:15You give the model a set of keys to choose from, essentially a computer use model.
7:05:19It gives frames as the input, so you can give it a text prompt as well.
7:05:24And you send it through API, and you say somebody waves at you, wave back.
7:05:28In the input space, the model understands that you have a grid action available, it
7:05:32will output the action associated with that.
7:05:35One way of intuitive understanding how this works, I've obviously simplified here because
7:05:42it's predicting the next token, not the next word, but bear with me here.
7:05:47LLMs took large-scale internet data, then trained it to predict the next text token,
7:05:52and now use it for writing software.
7:05:55These are all workloads that are really, really well fit for futures that are not simultaneously
7:06:00unfolding as you are predicting.
7:06:02Code is turn-based.
7:06:04You can say something, the model will do something, you can say something again, the model will
7:06:08do something again.
7:06:10And you can use it for lots of valuable work, but at the end of the day, because it's turn-based,
7:06:15it's very, very difficult for it to generalize to environments, especially that include space
7:06:22and time.
7:06:23So our models, the way that they work is they're continuously receiving frames or receiving
7:06:31batches of information from the camera of the robot, or it could be a screen.
7:06:36And it predicts everything as if it were just a video game.
7:06:41So you can think of the way that Anthropic focused on just nailing coding.
7:06:47So they were never frontier and just base text generation.
7:06:51They always focused on being the best at generating code.
7:06:53And then the bet that they made is that more people would start bringing more problems
7:06:57into coding space.
7:06:58If you think of general intuition, our bet is that you can, as humans, we are generally pixel-to-action converters, plus senses, which in many cases you can convert into pixels as well.
7:07:10And you can output actions at the same time.
7:07:13Those actions are, in this case, either keyboard and mouse or game controller.
7:07:16So the output tokens of the model are essentially equivalent to that of enhanced computer use model with more actions on the output space to internalize it.
7:07:25So you send frames, and you get actions.
7:07:28This works, again, because every single thing that you see here can control all of these different embodiments.
7:07:35So, as humans, we do not know how to predict motor torque.
7:07:45We do not know what value to send to a machine.
7:07:49There's this beautiful device that has been made for many years, which actually does that work for us so we can control them.
7:07:56Most robotics companies today are trying to solve the problem at the end-to-end level,
7:08:01trying to predict exact poses or exact values in the motor,
7:08:06instead of just looking and picking up the thing that every robotics company has built
7:08:13to generalize our very limited abilities to have physics understanding and predict exact values,
7:08:22and solve for it.
7:08:24And so our approach is, let's just use that.
7:08:28And so Medal, at the moment, sees about a billion videos uploaded per year.
7:08:36This year we're on track for three billion,
7:08:39which lead to over a trillion and a half action tokens per month.
7:08:44So just for comparison, to think about the bet,
7:08:46the total amount of data that Frontier Labs use today to train robotics models,
7:08:50we collect in, at the moment, half a day.
7:08:53And so the type of bet, and again, think of the fact that humans can use the exact same
7:09:01controllers and their eyes to play video games that they can't help upgrade robots.
7:09:06It is the same thing.
7:09:07We just bet on scaling pixel space the same way that anthropics killed coding space, and
7:09:13betting that people will just, as we scale data compute into pixel space, that people
7:09:18will bring more problems into pixel space.
7:09:19And so what happens?
7:09:25of a sudden you get an incredibly general agent that can go and solve problems on computers
7:09:35in the real world.
7:09:38in addition, similarly to how Anthropic focuses on doing coding environments, we focus
7:09:44on world models, which most of you know is for, the Mirai release world models, to then
7:09:48generate additional environments for these models to learn in.
7:09:51One way of internalizing a big advantage of this approach against LLMs is if you're an
7:09:58LLM company and you have to bet on the ability to generate environments for your models to
7:10:03learn, you have two problems.
7:10:05One, you actually need to spend the compute to simulate environments, and the more realistic
7:10:09you try to simulate, the more expensive that gets.
7:10:12and so imagine you want to learn a new thing
7:10:15you want to learn that new thing
7:10:17in the exact input space of the human
7:10:21so if we are learning from pixels
7:10:23we're learning by looking around
7:10:25if I'm trying to communicate something
7:10:27I want my robot partner to observe that exact same thing
7:10:30and so what I don't want
7:10:34is for that to have to go through an LM
7:10:36for a digital twin to have to be created
7:10:38for the model to have to get deployed
7:10:40for it to be a bunch of verifier checks
7:10:42whether or not things are equivalent
7:10:43and then for the robot to learn much later.
7:10:46And so one way of thinking about it is
7:10:47when you can learn in the native modality of the human,
7:10:50you can all of a sudden start solving a lot more problems
7:10:55a lot faster.
7:10:56What you'll see when these models come out
7:10:57is they're significantly faster than any LLM
7:11:02at doing these things.
7:11:06Because games are so action-dense,
7:11:08So what you see, right, is one thing that's interesting is you saw, for instance, the model predicting multiple actions at the same time.
7:11:16We're able to take that action density from gamers and convert them into really complex robotics workloads.
7:11:23So, for example, if you are operating a drone and you need to make lots of little adjustments, you really, really, really want to start with games.
7:11:30You don't want to start with teleoperations because the human will just take a lot less actions.
7:11:35It has a lot less information.
7:11:36You want a model that can predict really high APM.
7:11:39And so the APM of the data set puts a lot of these problems all of a sudden in reach
7:11:45so that it can do a lot of these actions simultaneously.
7:11:47And as I mentioned, the model doesn't just understand the key it's predicting.
7:11:51It also understands the semantic meaning associated with that key it's predicting, which is really
7:11:55important for things like interpretability.
7:12:00So we will be releasing the models this year.
7:12:04we are very happy
7:12:07I think the correct word would be
7:12:09that we're stunned
7:12:11by the fact of what these models can do
7:12:13it is
7:12:16this is a
7:12:17live stream so I unfortunately couldn't share
7:12:19the release videos without
7:12:21breaking the surprise but if you're in New York
7:12:22we are also in New York
7:12:24we have started doing a few demos
7:12:27of the model so if you can
7:12:28know somebody on the team reach out and we can start
7:12:30It's showing you some of the capabilities live.
7:12:34But we have essentially one model which can play video games at the highest level
7:12:38and control over 10 types of robots using the exact same primitives.
7:12:44So pixels in, actions out, completely real time.
7:12:47And we'll be rolling out early access to these models over the next few months.
7:12:52We already have some customers that are on them, but it's still private,
7:12:56so you're not hearing too much about it.
7:12:57But if you scan this QR code, you'll be able to get the models because we go by who signs
7:13:06up on the wait list at which times.
7:13:07So this is a great moment to get in touch.
7:13:11As I mentioned, we are in New York.
7:13:12What you'll find is similar to how Jev and a lot of these decision-making models have
7:13:18kind of opened people's eyes on what you can do when you have a new architectural primitive.
7:13:22People are ready
7:13:23to do away with the unpredictability of an LLM and put something in that is more reliable and faster and you understand how it is going to react as opposed to having to work around it.
7:13:33If that resonates, these models are exactly what you're looking for. And all of a sudden you can start exploring the environments that you generate with LLMs.
7:13:45All of a sudden, one of the use cases that I'm really, really excited about is, well,
7:13:50these models, they can take actions as if a human was on the interface.
7:13:54And so if you're doing UX work and you're trying to understand, is this an intuitive
7:13:59interface?
7:13:59Well, this is a very interesting way of solving the problem.
7:14:02So all these problems that LLMs can't solve because they can't actually explore like a
7:14:06human, you can use these problems and start using these models for.
7:14:11So the way that they're going to be released is we still expect you to use an orchestrator model.
7:14:18So you may use something like Gemini or Astra in order to do long-term planning and everything.
7:14:23And you'll be able to plug these into your workloads.
7:14:26And we're actually, the models are so general.
7:14:28It is genuinely going to, I think, feel like the early LLM days when you have a new toy
7:14:36and you just want to figure out what it does and all the things you can use it for.
7:14:40my reaction was like that
7:14:42when I first started using the checkpoints
7:14:44and I think you'll have the same reaction
7:14:48and I think a lot of you will
7:14:50just like with LLMs
7:14:51if you're a bit early and you start understanding these primitives
7:14:54I think you'll understand
7:14:57that you can even build lots of businesses on top of this
7:15:00think about for instance
7:15:04a science lab
7:15:06all of a sudden if you can reliably
7:15:08orchestrate robots in space and time, and they can take text instructions and do things.
7:15:13All of a sudden, it's a recursive problem, right?
7:15:18Robotics is interesting because one of the big problems of solving robotics is making
7:15:22more robots.
7:15:23And so there are all these businesses that, because it's so bottlenecked by intelligence,
7:15:28are going to emerge just from solving this one simple problem, which is pixels to actions.
7:15:34And I think if you're early on getting your hands on these, it will have a similar effect
7:15:39on getting your hands on early LLMs.
7:15:44I am most excited also, one of the things that we're working on which is interesting
7:15:49is if you have any friends or family who are in some way need accessibility help for using
7:15:57their computer, because these models can use computers like a human, all of a sudden, for
7:16:01For instance, if you only can use one arm, all of a sudden the model can allow you to
7:16:07play video games because you can just control the mouse and the model is predicting the
7:16:13actions for your keyboard.
7:16:14Because the model also understands which actions you're predicting, because that's the input,
7:16:19it's observing as it's acting, it will actually just not predict the things that you're doing
7:16:23and it will just predict the keys.
7:16:26It has all these downstream effects of things that you can build on top.
7:16:30I'm an engineer.
7:16:31If you're interested in building in this space, this is going to be the most interesting toy
7:16:37that comes out this year.
7:16:39I'm fairly certain.
7:16:42I also think a lot of the initial usage will sit in simulation.
7:16:44If a lot of you are into generating environments with Astra or Gemini, it's perfect.
7:16:48Now all of a sudden you can have something that can explore it and you don't have to
7:16:51do it yourself.
7:16:52itself, and it's perfect timing because of all the environment generation capabilities
7:16:59going into these models.
7:17:02So really quickly before I wrap up, I want to talk about the team.
7:17:06We are based in New York City.
7:17:09The Medal team and the general intuition team is here in New York City, so if you're here
7:17:13you should reach out to us and we can both show you the models, especially if you want
7:17:18to join the team, I think we'll prioritize even higher.
7:17:24But we really are looking for people who, A,
7:17:29want to understand these models as much as we do.
7:17:31So if you're really, really good at generating
7:17:33novel environments, typically if you have some sort
7:17:36of research background, but I don't have a research
7:17:38background, so that's OK.
7:17:40If you come from an engineering background
7:17:42and you're very happy to learn, this is fine too.
7:17:45And ideally what we want is somebody who has experienced shipping end-to-end AI products,
7:17:55but it doesn't have to be on the research side.
7:17:57So we just want to hire people that understand the entire thing.
7:18:02Let's see.
7:18:04We have three teams.
7:18:05So one is role modeling, the other is the policy, so the agent, and the other one is
7:18:09working on essentially the data generation and the environment generation.
7:18:13If you are an engineer, the best one to join is the environment generation team.
7:18:18And then you grow into getting access to everyone.
7:18:24I'm very, very excited for November.
7:18:26I really hope that you'll be on the lookout.
7:18:30As I mentioned, it will be either late November or early December is the current planning.
7:18:35One more thing.
7:18:36We are going to organize three hackathons.
7:18:39The first is in New York City, it will be mid-November.
7:18:46If you sign up for the partner wait list, we will send out some emails so everybody
7:18:49can get access.
7:18:51We hope to see everybody at the hackathons.
7:18:53I think it will be the first time to get your hands on them the way we are playing with
7:18:56them internally now.
7:18:59And there will be one in New York City and one in London.
7:19:01So if you are in either of those cities or want to travel to either of those cities,
7:19:04those would be good times to meet the team.
7:19:09Yeah, let's see.
7:19:10I have time for one or two questions,
7:19:12and then I think we can wrap.
7:19:17Let's see.
7:19:23How is it different from JEPA?
7:19:26Yeah, how is it different from JEPA?
7:19:27So JEPA doesn't train alongside the action labels,
7:19:30so they bet on inferred action labels for the most part,
7:19:33which I think, one of the ways of thinking about it
7:19:34is JEPA I think in the limit is the more correct approach
7:19:37but it's just a lot less practical in the short term
7:19:38because you need to bet on a separate
7:19:40scaling law on the action inference itself
7:19:44and
7:19:46we really like
7:19:47JEPA as a concept, we think it's a
7:19:49you know, we use some of the
7:19:51things in the models
7:19:52and
7:19:54but at the end of the day it's an approach
7:19:56not a product and I think we'll
7:19:59you know, borrow
7:20:01concepts both ways
7:20:04one way of thinking about it is
7:20:07because we have so much action data
7:20:09let's say you're flying a plane
7:20:11and you're moving the rudder in the back
7:20:13there's no way of being able to
7:20:15tell that from the video frames
7:20:17it's very very difficult
7:20:18so our mode on having the action data
7:20:20really transfers better to
7:20:23action sequences than it does
7:20:24to world models and to generating
7:20:26the pixels and that's why
7:20:28we just went all in on training these general
7:20:30foundation models for action predictions
7:20:32and we use all sorts of techniques to do world models.
7:20:34You know, we are own.
7:20:36We really like other companies building them as well.
7:20:40So, great.
7:20:43One more and then I've got to run, I think.
7:20:45Great.
7:20:49All right.
7:20:49Thank you, everyone.
7:20:51Have a good one.