Machine transcription with reviewed terminology and names. Some recognition errors may remain. Timestamps refer to the livestream; subtitle downloads are timed to the session clips.
4:02:28So I really love this article from Hannes at DuckDB, where he asks if we lost a decade chasing distributed architectures that presumed compute and storage were slow and expensive.
4:02:40Capability in every era, though, defines architecture and tooling, and the tooling lags behind consistently.
4:02:46We first made compute cheaper than storage, and then we gave it to everybody, and then we made it faster.
4:02:52And every single time, architectures undergo this massive change.
4:02:56All of our data infrastructure today is built on the idea that transformation is expensive.
4:03:02What if that wasn't true anymore?
4:03:05I believe we've solved the final bottleneck in transformation, general intelligence or judgment,
4:03:11and we've made it accessible on tap all along the Pareto frontier, which puts us right on the verge of a paradigm shift.
4:03:19So in this talk, we're going to cover why single ontologies always fail,
4:03:23the
4:03:23three roles models play in pipelines, intersecting model priors for better results, and Pareto surfing, how today's models can tune a workload for cost, speed, and accuracy all at the same time.
4:03:37Here's a quick example.
4:03:38When Jeff launched, we already had an entity resolution pipeline running, working out Ohio's campaign finance records and whether they belong to the same person, company, or committee.
4:03:49It was projected to cost about $10,000.
4:03:52Our systems took that new model, worked out where it fit, tested over a dozen approaches, and integrated it.
4:03:59Ten days after that first call, we had final ground truth for every donor case in Ohio under $800.
4:04:07That is the power of Pareto surfing and just-in-time transformations.
4:04:11So, let's get into it.
4:04:16Ontologies are the enterprise version of mind maps.
4:04:20It's this tar pit that sucks us all in, including me.
4:04:24I talked about a single universal schema when I founded Southbridge two years ago.
4:04:30The popular conception, and it's not wrong, it's just a small part of the picture, is that migrations and ontologies fail because of a lack of buy-in.
4:04:38And they're abandoned halfway through, that organizations and people never switch over.
4:04:42All of that is true, 100%.
4:04:45But buy-in isn't the primary reason.
4:04:48if you could integrate and migrate all of your information into a single super schema in the blink of an eye,
4:04:54you still have to contend with the truth that there is no super schema.
4:04:59There actually are four schemas.
4:05:01The first one belongs to the source, wherever the information comes from.
4:05:06Let's take temperature as an example.
4:05:08Say I ask you to write down the temperature.
4:05:10The source schema is whatever you have access to.
4:05:13Your phone gives you your region's temperature, sensor on your desk, which is less accurate, but it's more local, or your watch.
4:05:20But even your patience in following through on my request is part of that source schema.
4:05:25The second one is the storage schema.
4:05:29There's only so much you can write down.
4:05:31You can't write down the firmware of the device you're using.
4:05:34You can't even write the time down to the second because you couldn't finish writing all of that inside of a second.
4:05:40This is the schema imposed on you by storage.
4:05:43The third one belongs to the decision.
4:05:46Why do I need you to write the temperature down?
4:05:49Maybe I'm figuring out what makes you comfortable,
4:05:51in which case I need temperatures from you spread throughout the day,
4:05:54and I need to make sure that it's you that's doing the measuring.
4:05:57Maybe I'm building weather migration maps,
4:05:59in which case I don't care who does the measuring,
4:06:01but I care a lot about your exact location,
4:06:04the time, the device you used, and whether that's changed.
4:06:08Or maybe I'm deciding whether to install sensitive equipment and where,
4:06:12and you yourself become this variable that I need to cancel out.
4:06:17There's a fourth one, though, which we'll get to when we talk about priors.
4:06:20It's a recent addition.
4:06:22The true problem is that you will never know all four schemas at the same time,
4:06:28except at the moment that the decision is being made.
4:06:30In almost every enterprise and every home,
4:06:33most of the data being recorded has little idea what it's going to be used for.
4:06:37Take a customer, the first box in every ontology.
4:06:40to billing a customer is whoever pays, to support it's whoever calls, to compliance it's whoever
4:06:47we're on the hook for. And the only time you know is when the decision is known. Should we refund
4:06:53this order? Can we extend this account more credit? Suddenly, what you need to know, how and to what
4:06:59degree, becomes extremely clear. This is why I was wrong. There is no universal schema. There is no
4:07:07concept of a customer that's divorced from the question that you want to answer. And pulling
4:07:12these schemas together is the process of transformation, of making information actually
4:07:17useful, taking the context that it was recorded in and merging it with the context of the decision.
4:07:23And that takes discernment. Doing that merge when the decision space is known instead of ahead of
4:07:29time is what I mean by a just-in-time ontology. So we'll come back to discernment with a story
4:07:35from my last job where most of my job was to make sure that certain numbers just did not exist ever.
4:07:43Before that, a little bit about me and us. We are best described as obsessives. Obsessives who
4:07:50embed intelligence into pipelines. Pipelines that can scale, that can run over and over again to take
4:07:56work truly off our hands, and pipelines that can mature in cost, performance, and speed all on
4:08:02their own. And most of the work we do in data breaks into three regimes. The first is write-ones,
4:08:09run-ones. If you do any kind of development, think of these as monster-scale immediately
4:08:14invoked functions. They're built for something single-use, like joining a data set, mining
4:08:19information, or answering one specific question, and then they get torn down. The second is write-many
4:08:26run once, where lots of smaller and larger workloads are built for one large common goal.
4:08:32The closest thing you might know is large migrations. Years of records, moved out of
4:08:37systems nobody fully remembers, lots of workloads built for one move and verified individually at
4:08:43source, checked against the others, because all of it only happens once. The third though, and this
4:08:48is bread and butter, is the most common, is write many, run many. These are repeatable pipelines
4:08:54that are built and maintained over time as we add more information in.
4:08:58And at Southbridge, we've moved so much work off the main thread
4:09:02and into these repeatable systems from benchmark design, tracking, coding,
4:09:07to making subtitles for movies that we want to watch.
4:09:10Almost everything we do in the modern world is a transformation of data,
4:09:14or it's bottlenecked by how hard it is to transform data.
4:09:17And in all of these cases, our job is simple,
4:09:19make sure people can rely on the results.
4:09:22In just two years, we've gone from figuring out how to make early 3.5 turbo level models
4:09:28reliable on things like healthcare, aging, mining research, to building Hankweave, our
4:09:34open source harness for data work, and then using that to get models to work together
4:09:38at terabyte scale.
4:09:39Today, we have systems that can self-optimize.
4:09:42You give them the problem, a way to fail safely, a place to work, and they find the shape of
4:09:47the solution.
4:09:48They pick the right models.
4:09:49They run the pilots.
4:09:51They scale up.
4:09:51And they Pareto-surfed their way to the best option they can find.
4:09:58So, story, at my last job, the question we heard most often was, can we make this decision data-led?
4:10:07And sometimes that was the right question when we had thousands of vessels on the platform.
4:10:11The problem is that we also asked it when we only had 50 users.
4:10:15And if you know statistics, you can explain really well why A-B testing 50 users is a bad idea.
4:10:21Not because you're not going to get a result, but because you will.
4:10:25So the only real option was to not produce a number at all, because the moment a number exists, it argues for a result.
4:10:34Today, though, it is worse.
4:10:36Interactive agents will always give you an answer.
4:10:39They'll give it to you quickly.
4:10:40You ask for a transformation, whatever, and you get a contrary and yes, sir.
4:10:44What this means is mistakes add up quickly.
4:10:47Moment in chat can be a prod nightmare forever, just waiting to be discovered.
4:10:52The primary reason that this happens is that intelligence, as it relates to data work today,
4:10:59occupies three separate roles that coding agents kind of mash into one context window.
4:11:04Let's pull those apart because it'll help a lot when we get to decision models
4:11:07because they fit into exactly one of these three.
4:11:10The first one is building and designing the pipeline,
4:11:13which is breaking down the problem, writing the early specs.
4:11:17authorizing spent. The second one, and this is usually confused with the first and given to the
4:11:22same models, is working inside the pipeline, actually doing the work, reading the PDF,
4:11:27writing to databases, checking results. Before we get to the third one, I want to make it clear
4:11:32that these two roles pull in very different directions. The first one wants slower models
4:11:37with heavier, thicker tokens, models that can think more, walk around a problem and see the angles,
4:11:44digest documentation, understand how these pipelines get built,
4:11:48and predict how something will do before it even starts, like opus or up.
4:11:53The models you want inside pipelines, though, are the opposite.
4:11:56You want them cheaper, faster, specialized, good at following instructions,
4:12:01repeatable workers with knowable defects.
4:12:03You see the same thing in nature.
4:12:05A leafcutter ant colony, for example, runs on four different sizes of worker,
4:12:09small, medium, high, X-high.
4:12:11As you watch any system that you design, review, or hear about, listen for what slots and where in this layer cake.
4:12:19It makes a big difference.
4:12:20Because we had this distinction, bringing in JEV in this newly exploding class of decision models was very easy because they're workers.
4:12:28They're built for quick contact with information, and they're deployed at the bottom end of large workloads.
4:12:35So third category, though.
4:12:36This is something we call the hill climbers or surfers.
4:12:39Models that can take a first one and self-optimize.
4:12:43Given the right knowledge, instructions, and an incredibly stable surface to stand on,
4:12:48they can try new things, vary budgets to limit cost exposure, debug quickly, take notes,
4:12:54surf their way, not just to the right solution, but the optimal one.
4:12:58We call that Pareto surfing, and we'll cover it at the end.
4:13:02But first, let's talk about our experience with Jeff.
4:13:06JEV launched on a Tuesday when we were deep into an entity resolution pipeline.
4:13:11You were working on donors in Ohio's campaign finance.
4:13:14And at this point, a lot of people have seen this chart.
4:13:17We talked about the results before and adapted some of the ongoing work to the data set.
4:13:22So you can download it for yourself, prompts
4:13:23and everything.
4:13:24What we didn't talk about is everything behind that one arrow. And what happened when we ran the same idea on the whole state? Here are all of the architectures we tried.
4:13:34We started with three designs on a small development set, a cheap reasoning model on its own, Jev with a reasoning model for anything it wasn't sure about, and a reasoning model proposing answers with Jev checking them.
4:13:47On about 200 held-out families, the cheap reasoning model on its own did as well as Fable for about 2% of the cost.
4:13:56Jeff first got the core answers right, but it missed nine household legs because it had confidently said no to every one of them.
4:14:03So we rewrote the questions without touching the models or the thresholds.
4:14:07The household question now said what counts is enough evidence, and Jeff went from no on all 13 development questions to yes.
4:14:14And as we scaled it statewide, we ran over a dozen rounds of such qualification.
4:14:19Each round fixed a definition, what a committee is, what a filer means, when two people live
4:14:25at one address, what does that mean?
4:14:26Every one of Ohio's 203,317 cases now has a label that says what the answer rests on
4:14:35and how far it was checked.
4:14:36This is the hierarchy we discovered for this specific problem.
4:14:40And here's everything we learned about putting decision models into pipelines.
4:14:44I'll leave this up so you can screenshot it.
4:14:46But here's where the money went.
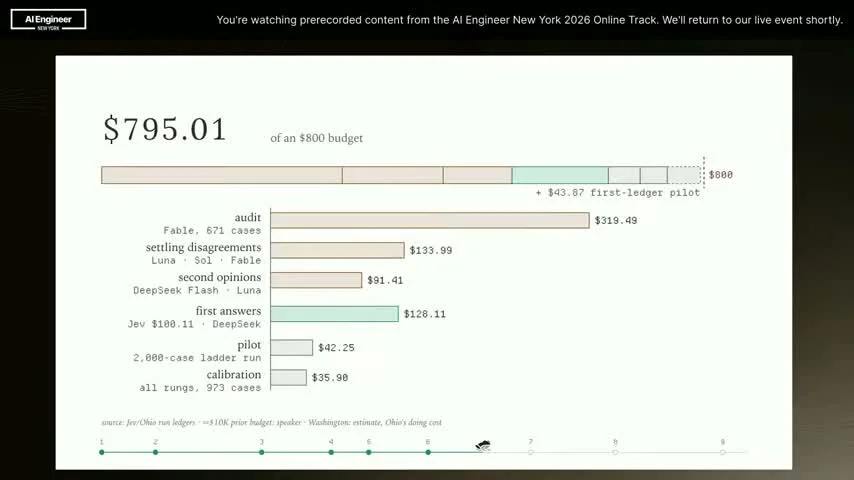
4:14:48The whole statewide job came to $795 on an $800 budget that was set ahead of time.
4:14:55Checking cost about four times as much as doing.
4:14:58$545 on second opinions, settling disagreements, and the audit against 128 for first answers.
4:15:05And before Jeff, we expected this work to cost about $10,000.
4:15:08And now that the pipeline is built and verified, we expect the audit budget for the next state to be close to zero.
4:15:15The most amazing thing is that our agent, 4A, running on Astra and then later on Opus, found most of these approaches incrementally on its own by building the system, running it, debugging it, and trying new things.
4:15:30It ran for 10 days, tried over a dozen architectures.
4:15:34Its hanks ran for more than 4,000 times, alongside 90,000 calls to Jeff, tried practically every model on the Pareto frontier.
4:15:42And the models inside those runs went through roughly 6 billion tokens.
4:15:46And once all of that was done, we wrote what we learned back into our library of agentic patterns.
4:15:52This work leaned on these existing ones, and we're adding new tested ones like the checking letter.
4:15:58This is, to me, the value of taking work off the main thread for humans and for agents.
4:16:05Because every single one of these iterations was a version-controlled Hank.
4:16:08They were easy to revert, understand, debug, and critique.
4:16:12So can models do this natively now?
4:16:16Not quite.
4:16:17They're missing four things, which we'll go over.
4:16:20And there's something that doesn't go away, though, as models get bigger and more capable,
4:16:24the prior.
4:16:26Just like humans, models bring their own priors, their beliefs about what should be in the world, to every task.
4:16:32This is the fourth schema that I mentioned before, the one the model brings with it.
4:16:39Bigger models, in a strange way, are worse at this sometimes.
4:16:43They hold on to their beliefs and argue for them even more vehemently.
4:16:47Here's a few that we ran into.
4:16:49One pipeline looked for in-kind spelled with an underscore.
4:16:53The file spelled it with a capital I and a hyphen.
4:16:56So the model counted 15,658 in-kind contributions as ordinary money.
4:17:02Didn't double check.
4:17:03The loan payment repayments also disappeared the same way.
4:17:06Another one tried four date formats when the file used to fifth.
4:17:1199.4% of the transaction dates then came out empty.
4:17:15And every row count and dollar matched, so the agent moved on.
4:17:20Several runs noticed that loan amounts were negative, decided that the sign was redundant, and stored the absolute value.
4:17:27A net of $784,000 became $5.3 million of debt in the end, validated by multiple models.
4:17:36And this is quickly becoming the largest class of error I see across companies at DataWork as models take over.
4:17:41Sometimes you can solve this just by not vibing, by checking results and applying human intuition.
4:17:47what you're actually doing there when you do this is interesting.
4:17:51You're intersecting your priors with the models.
4:17:54In that first example, any human would catch missing in-kind contributions,
4:17:59even you campaign finance or think to check.
4:18:02It's how we found it.
4:18:03But humans, speaking as a human on this particular task, are expensive.
4:18:07They are slow.
4:18:08They pause timelines.
4:18:09They're even more non-deterministic than models, and they hate interruptions.
4:18:14but it turns out you can also get really far with cross model prior intersection on our 200 held
4:18:20out families jev and luna agreed on 194 and none of those shared answers was wrong every error sat
4:18:28in the six families where they disagreed models from different families different pedigrees tend
4:18:33to disagree more and have different priors than models in the same group for example the exception
4:18:39I'm not going to say who are models that are distilled outside the same company.
4:18:44So with that kind of work, you can shrink the surface quite a bit and the errors along with it down to a much smaller but persistent class of problems that apply to LLMs as a species.
4:18:55So in one benchmark, four different model families produce the same total down to this end because they all shared a sign convention that the answer key didn't.
4:19:03And once you get that far, the only way forward is to list them, look out for them, and apply specific solutions.
4:19:12So going back, what are the four things we're missing to be able to self-optimize?
4:19:17Number one is a stable deployment surface.
4:19:20We use Hankweave for this, a harness that takes the fast-moving surface of agent runtimes like CloudCode and Py,
4:19:26and that exposes a consistent, well-tested log and API interface with checkpointing,
4:19:32rollback, budget enforcement, everything built in. Something you can build on.
4:19:36But other things fit this description. To be fair, for headless data work,
4:19:41Hankweave, I would say, is still the oldest, most stable, and the most open.
4:19:44I'll leave the skill up if you'd like to try it.
4:19:47Number two is some way to bound your experiments. You can't test unless you can control cost,
4:19:53time, and access as resources. The third one is know-how and methodology. We found that this new
4:20:00class of models can take everything we've learned from two years of deployments, agentic patterns,
4:20:05debugging techniques, prompting, and apply it to complex problems. With the right abstraction layer,
4:20:10you can express it very token efficiently and the models can implement it. The fourth and the most
4:20:16important one is a failure surface. Archimedes said, give me a place to stand and I will move
4:20:22the earth. And in our case, we haven't met a problem or a constraint that we couldn't iterate
4:20:26ourselves to solving, given a stable stack to build on and a failure surface to iterate against.
4:20:32That last one has been the hardest to put into words and into tooling and instructions that helps
4:20:38models get there. The current best models are still only barely good at this, sparks of intelligence,
4:20:44so to speak. The whole process, though, involves going through six stages. First, we spec the job
4:20:50and we split it. For Jeff, that means splitting some 800,000 rows into 200,000 smaller specialized
4:20:56cases, and each of those cases into typed questions, what kind of donor, one donor,
4:21:02you know, different, different questions that needed to get answered. Then we decide the failure
4:21:06surface. In this case, we ran good models on a small slice of the data, with some of it being
4:21:10manually checked, to set a baseline that we can fail against. In other cases, we've set automated
4:21:17failure systems, we've set schema checks, we've also covered behavior as a thing that we can
4:21:22measure against, but it's very important to have to define a failure surface before you ever start.
4:21:28But now comes the fun part. We run minimal bounded pilots to test architecture. And once
4:21:35something starts working, we move those checks into rigs, code that runs between bounded work
4:21:40segments that we call codons. These codons are then reused, looped independently, validated,
4:21:46and placed in sequence. Finally, working pipelines get deployed to production where they can slowly
4:21:53mature. And that middle part is where the surfing happens. We find an architecture that gives a
4:21:59solid result. We use it as a baseline and we swap models and some other parts for faster,
4:22:04cheaper options, compare against known intermediates, tighten the requirements for
4:22:08success, each time moving closer and closer to the ideal. And you just watch the frontier move.
4:22:14Being able to break a complex problem into pieces means each piece can move to its own best position, as Adam Smith would say.
4:22:23In a system like this, ontologies exist as intermediates between intelligence and result, which makes them easier to reuse.
4:22:31That's the other half of what I mean by just-in-time ontologies.
4:22:34It's built when the job needs it, kept with its receipts, and reused when the next job needs the same thing.
4:22:40And once you have those, you can make these things cheaper. You can run them in parallel across data sets to scale up.
4:22:48I close with an apology, right, that the answer is there is no ontology. Not a universal one, at least. There never was one.
4:22:56The good news is that this makes every ontology and schema valid, as long as you can label and preserve the context around it.
4:23:03And if we can harness this cheap intelligence that's starting to percolate through the world around us, we're rapidly approaching a future where any information in any format is made as useful as it can be.
4:23:15And at Southbridge, we're working as hard as we can to make that future a reality.
4:23:19Thank you.