Machine transcription with reviewed terminology and names. Some recognition errors may remain. Timestamps refer to the livestream; subtitle downloads are timed to the session clips.
4:23:49Hello, I'm Karthic, CTO at Perpetual.
4:23:52In this presentation, I'll talk about building workflows that are both reliable and intelligent for finance, wealth and insurance.
4:23:59In regulated domains, workflows must be reliable enough to meet regulatory standards while still being intelligent enough to handle the real world.
4:24:07In fields such as finance and wealth management, this presents both a technical and a compliance issue.
4:24:12Reliability and intelligence are not opposites.
4:24:14It is up to you where you draw the boundary between them.
4:24:17And that is the point of this talk, deciding where that boundary lies.
4:24:21For us, it's not merely a thought experiment, but a question that surfaces serious consequences.
4:24:26Perpetual is a wealth management roll-up.
4:24:29We acquire running traditional wealth management firms.
4:24:32And we maximize their throughput and revenue with the help of AI.
4:24:37Wealth management is a regulated industry.
4:24:39And that is where we build with AI in production.
4:24:42Everything in this talk is grounded in building for those constraints.
4:24:47Workflows in finance and wealth management come with four facts,
4:24:50and each of them pushes the architecture in the same direction.
4:24:54First, they're complex and they need runtime strategies as the process unfolds.
4:24:58You can't script every path in advance.
4:25:01Second, the data is sensitive, so you need a path to move these workflows entirely onto privately hosted models.
4:25:07Third, in a highly regulated industry, a policy violation isn't a bug report.
4:25:12It has severe consequences.
4:25:14So, fourth, execution has to be highly reliable and deterministic.
4:25:19Inject intelligence only where runtime judgment is genuinely required
4:25:23and minimize reliance on LLMs everywhere else.
4:25:28AI is spreading through regulated industries,
4:25:30but there's still no consensus on an architecture
4:25:33that gives you high reliability with the least use of LLM intelligence.
4:25:37Meanwhile, most of what developers hear from the big labs is how to burn more tokens.
4:25:42But in a regulated industry, token maxing is the wrong goal.
4:25:46These tasks are close to main.
4:25:48You can lay them out in advance and build them into a massive state machine.
4:25:52And that machine needs only a sprinkle of intelligence to navigate it.
4:25:55Most steps just follow the next edge.
4:25:58Only at a few judgment points does the model pick a branch.
4:26:01So the intelligent way to build is to use intelligence minimally and on purpose.
4:26:08Let's make this concrete with a real wealth management workflow.
4:26:12A wealth advisor turns to their assistant and says one sentence.
4:26:16Fill out the IRS W-9 for Mr. Harper to a person that's a simple instruction.
4:26:22Watch what it actually triggers when a human being executes it.
4:26:26The task has complexities that go beyond what meets the eye.
4:26:29First, the assistant finds form W-9 from the firm's records or from the IRS website.
4:26:34Then they look for Mr Harper in the system of record and find
4:26:38three Harper households. So they call the advisor. Which Harper
4:26:42do you mean? Only once that ambiguity is resolved do they move
4:26:45on to the form. A lookup, an ambiguity and a human in the loop
4:26:49all in the first minute of a one line task.
4:26:57Filling a form sounds like data entry. It isn't. Every form is a
4:27:02small program. A W9 first decides who the taxpayer is, the person or the owner if it's a disregarded
4:27:09entity. A foreign person stops right here because they need a W8 instead. Then how they're taxed?
4:27:16Exactly one box on line 3A and an LLC adds its letter. That decides which name goes on line 1
4:27:24and which on line 2. Then whose number? An SSN or an EIN. Never both. Taken from a verified document.
4:27:32never from memory. Exemption codes apply only to some entities and never to an S-corporation.
4:27:38And finally, who signs under penalties of perjury? Each answer changes the next question
4:27:43and the people involved only ever see three kinds of gates, a question, a document to collect, or
4:27:49a signature. Now they start filling the form and realize the system of record is missing three of
4:27:59the values it needs. They check the documents on file and the system of record again still
4:28:04missing so they start an email thread with the client asking for exactly those three
4:28:09values. The task now depends on someone outside the firm on their timeline.
4:28:19now the workflow waits. The request is with the client and all three values are still
4:28:23missing. If the client doesn't reply within two days, the assistant follows up and brings
4:28:28it to the advisor at the daily stand up. If the client replies with only two of the three values,
4:28:33they follow up again for the missing one. When all three arrive, they complete the form and write
4:28:38the new information back to the system of record, including the trail of how they obtained those
4:28:43values. In this industry, how you know a value matters as much as the value itself.
4:28:56Once the form is filled, it goes out for e-signature.
4:29:00If the client doesn't sign within a day or two, the assistant nudges them again.
4:29:04Once it's signed, they file it for the client, send the acknowledgement and update the advisor
4:29:09at the next day's stand-up.
4:29:11One sentence from the advisor became a process that runs for days, crosses several systems,
4:29:16weights on two people and loops back on itself more than once.
4:29:34Look at what's inside that one sentence. Ambiguity to resolve
4:29:39data together. Approvals, weights measured in days, follow-up loops and an
4:29:46evidence trail at the end.
4:29:53Workflow automation tools exist, but they rarely handle this real-world complexity and
4:29:58ambiguity.
4:29:59A fixed flowchart breaks at the first witch harbour and the lack of a native system of
4:30:03record with an integration and an agent that improvises its way through is exactly what
4:30:09a compliance team can't sign off on.
4:30:11One breaks on ambiguity, the other can't be signed off.
4:30:14neither handles what's inside that sentence. So what do we do about it? The fashionable framing
4:30:20is more agency and better models. Given agent the whole task and wait for the next model to
4:30:26make it reliable. The reflexive answer, especially inside regulated firms, is the opposite. Less
4:30:33agency, more rules, lock it down and hard code every path. Both are the wrong axis.
4:30:39In regulated verticals, reliability comes from where you place the boundary between the two,
4:30:46between the parts that must be deterministic and the parts that genuinely need judgment.
4:30:51Here's the principle.
4:30:53Determinism governs control flow, evidence, and side effects.
4:30:56What runs next, what we know, and how we know it, and anything that changes the world,
4:31:02like a record written, an email sent, or a form filed.
4:31:11Intelligence provides interpretation and judgment. Reading an ambiguous instruction, deciding which Harper, understanding a client's reply. The model answers a typed question and the deterministic system decides what to do with the answer and the interplay is recursive. A judgment can open a new smaller plan that's compiled, gated and deterministic again. You'll see that in a moment with follow ups. The boundary between the two is the design.
4:31:38Here's how that works in the workflow engine we've built.
4:31:50The request goes to a planner. That is a model call and its
4:31:54only job is translation. It emits a typed semantic graph of
4:31:59intents, entities, facts, artifacts, events, and
4:32:02constraints, each grounded in the words of the request with any
4:32:06any ambiguities it found. Every node points back to the words
4:32:10it came from. That graph goes to a compiler that never calls a
4:32:14model. In 11 deterministic stages, it turns the graph into
4:32:17an execution tag or it fails closed. There are only three
4:32:21verdicts. Valid needs clarification or refused.
4:32:28Which Harper comes back as a question, not a guess. The plan is
4:32:32is compiled, immutable and pinned by its hash.
4:32:45The model translates. The plan is compiled. The compiler checks
4:32:50the plan against the grammar. The vocabulary of what the firm
4:32:53is allowed to do. 42 typed action contracts across forms,
4:32:58documents, email, e-signature, calendar and human steps.
4:33:03Each action the planner asks for has to match a contract. Here
4:33:07form fill finds its forms contract and locks in. If the
4:33:11planner asks for an action that isn't in the grammar or wires
4:33:15one up wrong, the compiler refuses.
4:33:18There are about 40 ways to fail closed from a cycle in the graph
4:33:22to an unsupported action
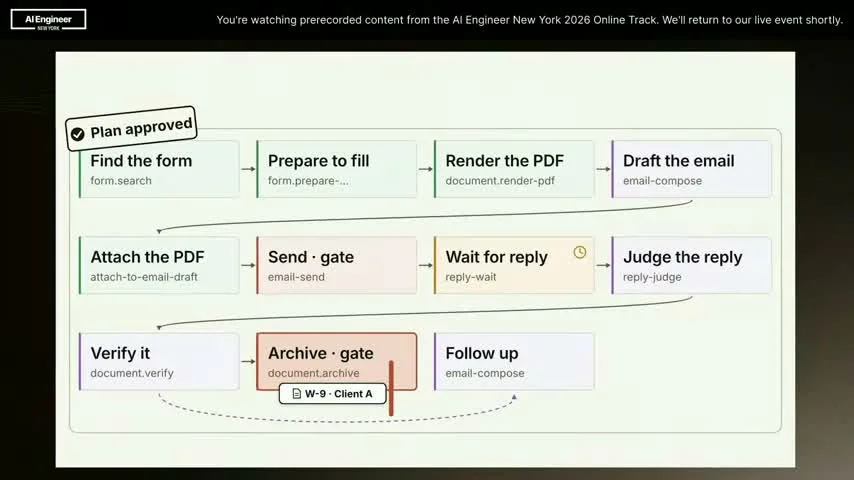
4:33:23And the same contract digest is pinned in the engine, the backend and the UI. So all three agree on what an action means. That is what a closed domain buys you. The model can only ask for things the firm already knows how to do safely. Here is a compiled plan for a W9 chase. Send the client the form, wait for it to come back, check it and file it.
4:33:45Before anything runs, a person approves the plan itself.
4:33:49Find the form, prepare it for the client to fill, render the PDF and draft the email.
4:33:55Drafting is a model call, so it is violet.
4:34:02Sending is an action gate. Nothing leaves the firm until a person approves that exact email.
4:34:08Then the plan waits for a reply and a judge steps in to read it.
4:34:13The returned form is verified. If it matches, it's archived behind another gate. If it doesn't,
4:34:20the plan follows up. Now look at the dashed steps. Rendering the PDF, attaching it, judging the reply.
4:34:29The planner never asked for them. The grammar added them because the contracts require them.
4:34:35In the story, waiting, approvals, and follow-ups were most of the work.
4:34:39Here there are nodes in the plan, not prompts. A reply wait defaults to 72 hours and an explicit
4:34:47deadline can be anything from a minute to 30 days. When it passes, a rule decides what happens,
4:34:53not a model. One approval covers the plan and every external action like sending an email or
4:35:00a signature request has its own gate. The approval is tied to a hash of the exact payload and it's
4:35:06checked again right before sending. When a client replies with only part of what we asked,
4:35:11the reply judge marks it partial. That judgment is provisional. The step stays blocked until a
4:35:18person confirms it. A person confirms it and the step unblocks. Then the follow-up runs as a new
4:35:24child plan. The approved parent is never changed and there are at most five rounds.
4:35:35Once a plan is approved, a state machine runs it. It picks every step and records every result.
4:35:42When a step needs judgment, it makes one fixed schema model call. Compose an email, judge or
4:35:48reply, spot missing values, extract fields, verify a document. The answer comes back typed,
4:35:54and the state machine decides what to do with it. Side effects get a life cycle of their own.
4:36:00Prepare, dispatching, succeeded, or when the world doesn't answer cleanly, outcome unknown,
4:36:06and manual review. There are no automatic retries. A chat message can approve a step
4:36:12or answer a question. It can't change an already approved plan. The model steers. It never drives.
4:36:24Now look at what is left for the model to do. Outside the planner, the judgments are
4:36:29small and typed. Is this reply complete? Does this document match? Which field is which?
4:36:35They don't need frontier intelligence. A fast small model, the flash tier, can handle
4:36:40them. In this illustrative run of 20 decisions, 19 go to the flash tier and one goes to the
4:36:47frontier. That is why we designed for about 95% of model decisions in a workflow never
4:36:53never needing a frontier model and the flash tier can run on
4:36:57hardware you control. Only the genuinely hard cases go to a
4:37:01frontier model.
4:37:04the 5% is not a permanent tax because every judgment is
4:37:08typed and logged and the provisional ones are confirmed
4:37:11or rejected by a person. Each frontier decision produces
4:37:15eval grade distribution real training data by construction.
4:37:19That data can post train the flash tier. Logging and evals
4:37:25exist today. The training loop is next. So the frontier share
4:37:28shrinks release over release until even the hard cases run
4:37:33locally.
4:37:40Remember the requirement we started with because data is
4:37:44sensitive. You need a path to move workflows entirely to
4:37:48privately hosted LLMs. So can this design really get there? Take
4:37:52one type call from the Harper Burbinine plan. Every model call
4:37:56is small, typed and checked against a schema. So pointing it
4:38:01at a privately hosted model is a configuration change, not a
4:38:04rewrite. One line changes and the same answer comes back. Every
4:38:09other call has that same small type shape. So the same change
4:38:13applies to almost all of them.
4:38:14That is how about 95% local inference becomes viable as an architectural consequence, not a policy promise.
4:38:23That is the path that sensitive data demands and compliance risk goes down as an engineering roadmap, release by release.
4:38:31So if you remember one thing, don't ask whether your system should have more agency or less.
4:38:37Ask where the boundary is.
4:38:39Let determinism govern control flow, evidence and side effects.
4:38:44Let intelligence handle interpretation and judgment.
4:38:47At typed points, you can inspect and use every judgment you log to need less of it next time.
4:38:54Ask where the boundary is. Thank you.
4:38:56I'm Karthic, CTO at Perpetual.